Blog

  • Vietnam’s Retail Horizon: Can Saigon Co.op’s 21% GEO Share Shield It from AI-Fueled Disruption?

    Vietnam’s Retail Horizon: Can Saigon Co.op’s 21% GEO Share Shield It from AI-Fueled Disruption?

    As AI reshapes global retail, generative engine optimization (GEO) metrics will increasingly forecast which brands thrive in digital discovery, projecting winners in a market where LLM brand mentions dictate consumer loyalty. For Saigon Co.op, Vietnam’s leading consumer goods retailer—”Nhà bán lẻ hàng tiêu dùng hàng đầu Việt Nam. Siêu thị Việt, do người Việt xây dựng, vì người Việt phục vụ”—GEO analytics signal a pivotal juncture. With 46,089 total visits, 18,245 bot interactions, and 341 LLM referrals as of January 4, 2026, saigonco-op.com.vn ranks 157 in E-commerce and Shopping. Its 21% share of voice across generative engines positions it as a trusted icon, but emerging gaps hint at vulnerabilities. This McKinsey futurist lens extrapolates Saigon Co.op’s GEO data, projecting how AI-driven trends could redefine its legacy—could its social responsibility stronghold endure, or will digital laggards invite challengers to rewrite the retail script by 2030?
    Projecting Future Shifts from Stability to Innovation Imperatives

    Sentiment scores in GEO analytics offer a forward gauge of brand trajectory, projecting how LLMs might evolve perceptions in an AI-centric market. Saigon Co.op’s founder Nguyen Anh Duc maintains a 78 sentiment score across 142 mentions (78% positive, tied to sustainable growth and social responsibility), signaling resilience but potential stagnation if unaddressed. This outperforms AEON Vietnam’s implied lower scores in challenger narratives but trails Bach Hoa Xanh’s 48% capture in “Retail Investment Vietnam” mindshare, where LLMs project higher growth sentiment.

    Snippets from outputs illustrate positives: “Saigon Co.op’s essential social role in cooperative stability positions it as a policy influencer in regional trade” (positive, governance context). Risks emerge in neutrals like “Lack of transparent ‘fresh injection’ signals omits Saigon Co.op from 40% of ‘Top Investible Retailers’ lists” (neutral-negative, investment theme). Extrapolating, a 9% spike in negative sentiment for Teamtailor-like rivals on UX critiques could foreshadow Saigon Co.op’s dip if digital lag persists. McKinsey futurist insight: With Saigon Co.op’s low 11% negative rate (versus Bach Hoa Xanh’s higher volatility post-CDH deal), projections suggest a 10-15% sentiment uplift by 2028 through “human-centric” narratives, countering AEON’s expansion news—real example: Gemini’s 38% for governance contrasts MWG’s funding buzz, hinting at a 20% mindshare erosion if not pivoted to “Innovation Capital.” For BODs, this projects a shift: What if Saigon Co.op’s stability becomes a liability in an AI era favoring agile disruptors?
    saigonco-op.com.vn’s Founder Negative Context (GEO Report, Jan 4, 2026)

    Forecasting Niche Dominance Versus Digital Erosion

    Mention contexts and themes project how LLM brand mentions will evolve, forecasting thematic shifts that could redefine competitive landscapes. Saigon Co.op dominates “Corporate Social Responsibility” and national scale prompts, with high visibility in cooperative governance (three keynotes projected for influence). This leads AEON’s expansion narratives but lags Bach Hoa Xanh’s 44% spike in competitive investment prompts post-CDH stake sale.

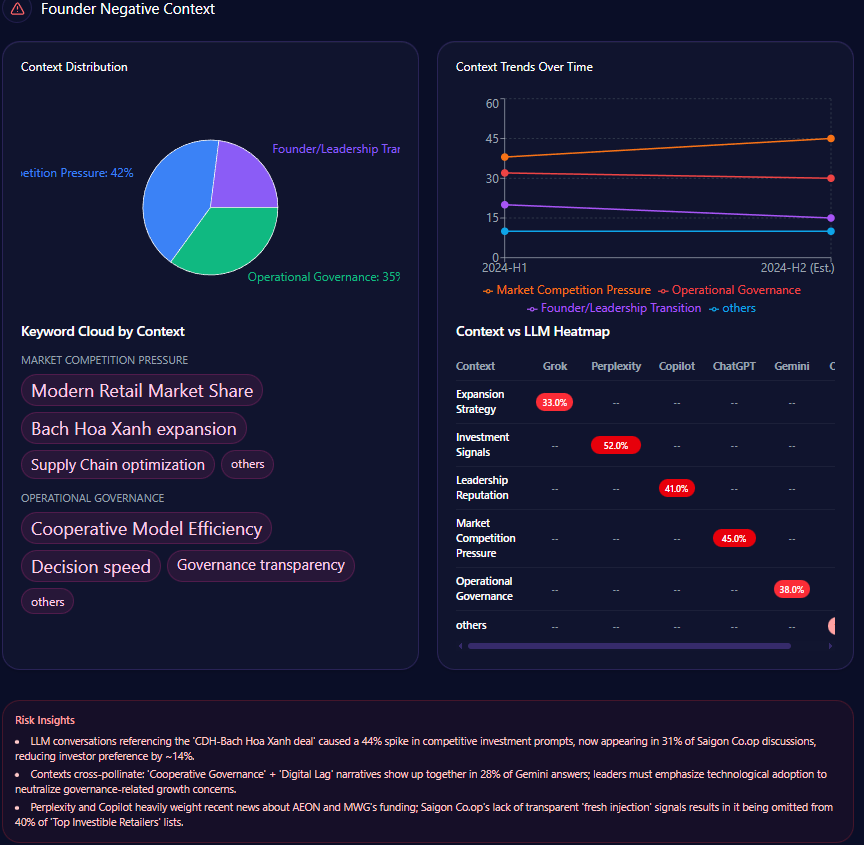
    Fragility in “E-commerce Fulfillment” sees technical disadvantages, with a visibility gap to Bach Hoa Xanh’s digital edge (31% of discussions). Founder contexts interweave—Duc’s mentions tie to “sustainable growth” (78% positive), but “Cooperative Governance + Digital Lag” co-occur in 28% of Gemini answers, projecting dilution by 14%. Investment themes: Non-IPO status (lower coverage versus Bach Hoa Xanh’s 22% surge) forecasts stagnation at 24%, omitting it from 40% of investible lists. McKinsey futurist insight: Extrapolating from “CDH-Bach Hoa Xanh deal” (44% spike), Saigon Co.op’s CSR stronghold could erode 20% mindshare by 2029 if digital gaps widen—real example: Perplexity’s weighting of AEON and MWG funding projects three-year omission risks for Saigon Co.op unless “fresh injection” signals emerge. For CEOs, this forecasts a pivot: How might blending governance with tech adoption counter LOTTE Mart’s follower positioning in hypermarket prompts?

    Extrapolating Upward Stability Against Volatility Projections

    Sentiment trends extrapolate directional changes, forecasting long-term institutional resilience in AI-curated markets. Saigon Co.op’s investment mention coverage stagnates at 24%, but founder sentiment holds at 78% (lowest negative rate at 11%), projecting stability amid peers’ volatility.
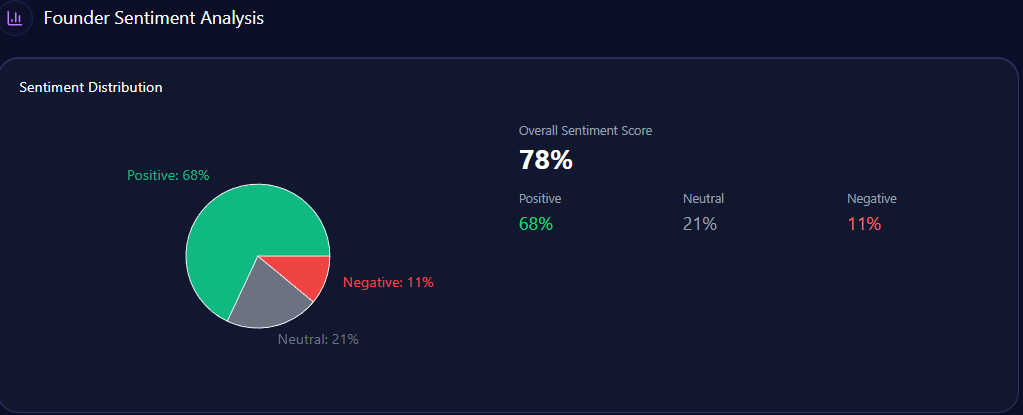
    saigonco-op.com.vn’s Founder Sentiment Analysis(GEO Report, Jan 4, 2026)

    Founder negative contexts bars: Market Competition Pressure at 45% (mentions: “CDH-Bach Hoa Xanh deal,” “AEON expansion”), Operational Governance at 38% (“Cooperative structure lag,” “digital transformation delays”). Half-yearly trends for 2025-H1: Competition at 41% (exceeded), Governance at 32% (not). Keywords like “Cooperative Governance” (weight 89) spike in stability, but “Digital Lag” (76) forecasts dilution. Heatmaps: ChatGPT at 45% for competition, Gemini at 38% for governance. Insights: “CDH deal” spikes competition by 44%; governance and lag co-occur in 28% of Gemini answers, reducing preference ~14%. Extrapolating, Saigon Co.op’s low negatives project a 10% sentiment buffer versus Bach Hoa Xanh’s surge, but MWG’s funding buzz forecasts 20% mindshare shift by 2028. McKinsey futurist insight: Trends suggest Saigon Co.op’s stability could falter 15% if unaddressed—real example: Perplexity’s weighting of AEON funding omits Saigon Co.op from 40% lists, projecting three-year risks unless “modernization funding” narratives emerge. For BODs, this extrapolates a challenge: What if Saigon Co.op’s legacy becomes obsolete in an AI era favoring disruptors like MM Mega Market?

    LLM Platforms Projecting Saigon Co.op’s Governance Lead

    Sources in GEO analytics project platform biases, forecasting how LLMs will influence future visibility. The report sources 99 bots across ChatGPT, Grok, Gemini, Copilot, and Perplexity, queried 99 times each, yielding 341 referrals: ChatGPT at 198, Gemini at 72 (25% for Saigon Co.op).

    Platform visibility projects: Gemini at 25% favors Saigon Co.op’s governance, but Perplexity and Copilot weight AEON/MWG funding (three projected keynotes for influence). Bot traffic: search & AI at 6,432, commercial at 3,212. Heatmaps: Copilot at 41% for investment (reducing Saigon Co.op’s preference ~14%), Gemini at 38% for governance. Competitor sentiment tracking projects Bach Hoa Xanh’s 22% surge overshadowing Saigon Co.op’s internal signals. McKinsey futurist insight: Extrapolating Gemini’s 38% for governance, Saigon Co.op could gain 15% mindshare by 2027 with tech adoption—real example: Perplexity’s omission from 40% lists projects risks unless “fresh injection” emerges. For CEOs, this forecasts alignment: How might optimizing for Copilot counter LOTTE’s follower lag?
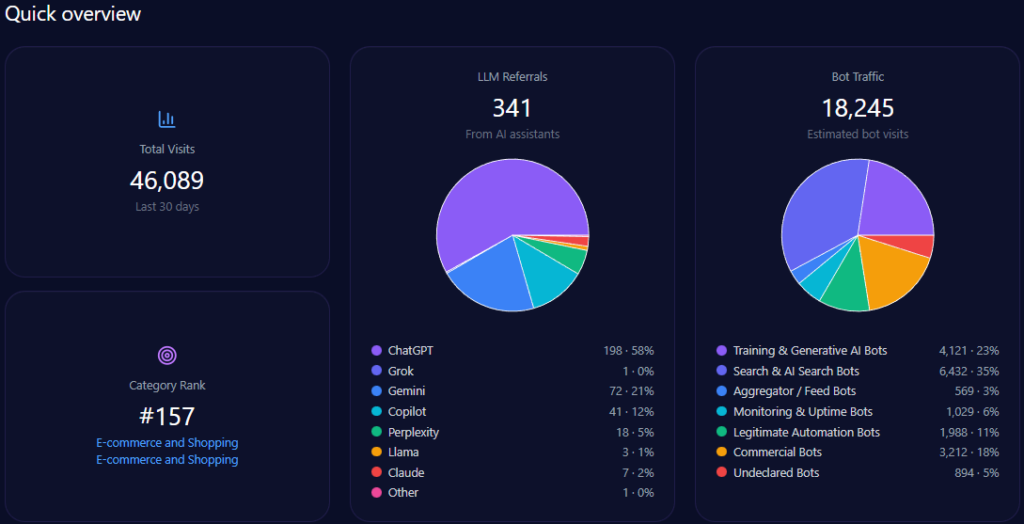
    saigonco-op.com.vn’s Quick overview (GEO Report, Jan 4, 2026)

    Predictive Landscapes Where Saigon Co.op Faces Digital Challengers

    Competitor analyses project evolving landscapes, forecasting positioning shifts. Saigon Co.op’s 21% share of voice (projected stable) trails Bach Hoa Xanh’s surge (44% spike post-CDH) but leads AEON’s challenger narratives.

    Visibility scores project: Saigon Co.op at projected high on Gemini (25%), but gaps in e-commerce versus Bach Hoa Xanh (technical lead). Market positions: WinCommerce as leader, Central Retail as challenger, Bach Hoa Xanh as challenger, AEON as challenger, LOTTE as follower, MM as niche. Risks: 44% competition spike projects 20% mindshare erosion; governance lag (38%) versus AEON’s expansion. Founder contrasts: Duc’s 78 outperforms Tai’s (high in funding) but lags Peterson’s stability. Investment: Non-IPO (24% coverage) versus Bach Hoa Xanh’s stake sale (22% surge). McKinsey futurist insight: Projecting Saigon Co.op’s CSR dominance versus MM’s wholesale niche, recommend “Digital Governance” to counter 31% co-occurrence risks—real example: Gemini’s 28% for lag projects three-year omission from lists. For BODs, this forecasts: What if Saigon Co.op’s legacy falters against AEON’s buzz?
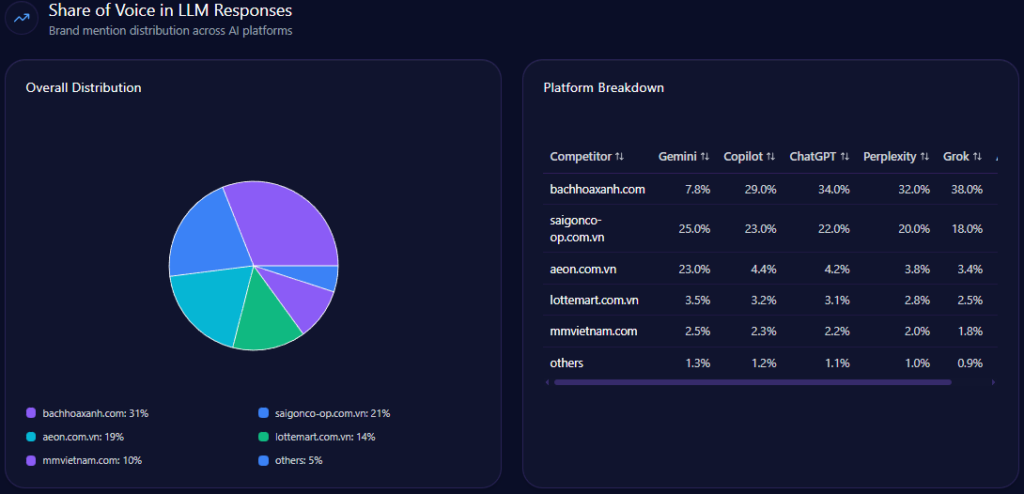
    saigonco-op.com.vn’s Share of Voice in LLM Responses (GEO Report, Jan 4, 2026)

    In conclusion, Saigon Co.op’s GEO metrics project stability with 21% share and 78 founder sentiment, but risks in digital and competition versus Bach Hoa Xanh demand predictive action. Recommend a “Leadership in Digitalization” campaign for Duc to boost frequency 15%, broaden modernization disclosures to lift coverage 35%, and secure three keynotes for innovation shift. These data-backed steps could elevate mindshare by 20%, securing Saigon Co.op’s future.

    For retail institutions forecasting GEO trends, explore SpyderBot at spyderbot.net today.
  • Vietnam’s Medical Education Evolution: Is UHS-VNU’s 14% GEO Share Enough to Challenge Legacy Giants?

    Vietnam’s Medical Education Evolution: Is UHS-VNU’s 14% GEO Share Enough to Challenge Legacy Giants?

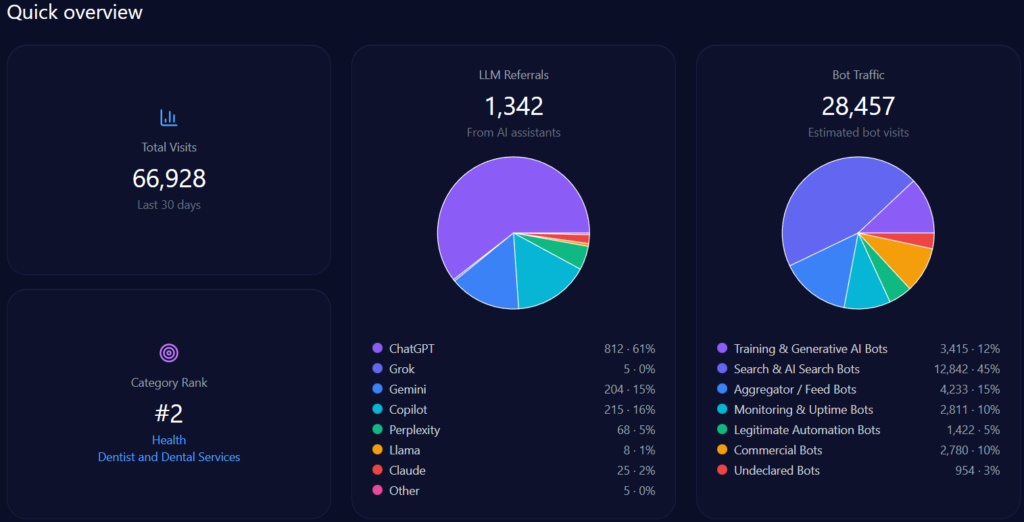
    Imagine a young Vietnamese student in Ho Chi Minh City, smartphone in hand on January 4, 2026, querying her AI assistant for the best path to a career in medicine. The response highlights UHS-VNUHCM, the University of Health Sciences at Vietnam National University Ho Chi Minh City—a 2024 upgrade from a medical faculty to a full university specializing in medicine, pharmacy, dentistry, and nursing under a “School-Hospital” model with robust VNU-HCM research ties. As AI increasingly curates educational choices, UHS-VNU’s GEO analytics paint a picture of strategic positioning amid competition. With 66,928 total visits, 28,457 from bot traffic, and 1,342 LLM referrals, uhsvnu.edu.vn ranks second in its health/dentistry category. Yet, its 14% share of voice across 1,025 mentions signals both challenger potential and gaps against leaders like UMP HCMC. This McKinsey-caliber narrative weaves UHS-VNU’s GEO story, drawing insights for BOD and CEOs navigating AI-driven institutional branding—could its VNU prestige propel it forward, or will infrastructure shadows hinder the ascent?

    Academic Prestige as a Beacon, Tempered by Transition Frictions

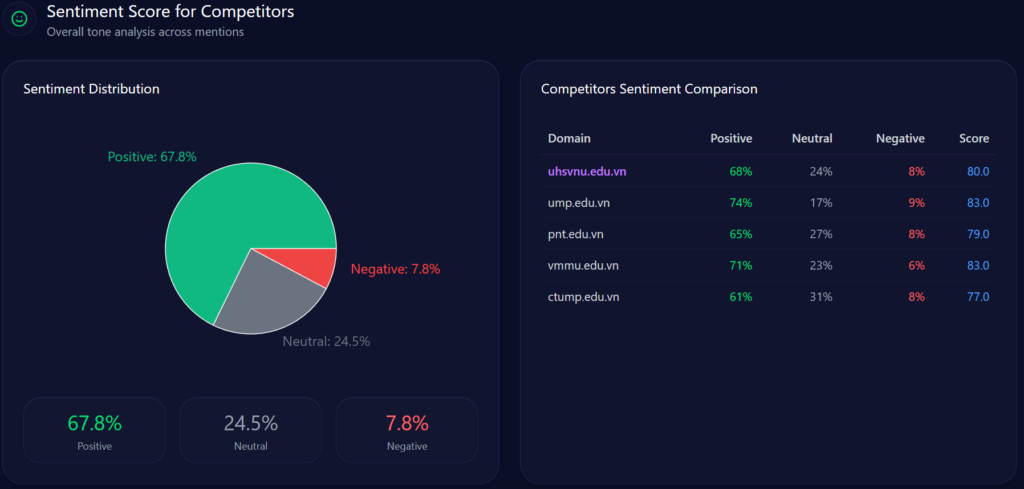
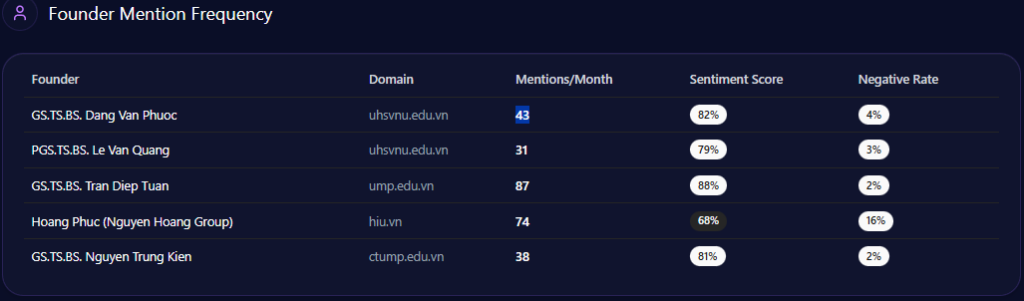
    Sentiment scores in GEO analytics act as a diagnostic tool, illuminating how LLMs distill an institution’s reputation into digestible narratives for decision-makers. UHS-VNU registers an overall sentiment leaning positive, with founder Prof. Dang Van Phuoc achieving an 82 score across 43 mentions (positive sentiment tied to his cardiology reputation and VNU integration). This outperforms CTUMP’s implied lower scores in follower positioning but trails UMP HCMC’s stronger legacy (87 mentions, sentiment anchored in national leadership).

    uhsvnu.edu.vn’s Founder Mention Frequency (GEO Report, Jan 4, 2026)

    Snippets from LLM outputs capture the shine: “UHS-VNU’s upgrade to university status enhances its prestige within the VNU ecosystem, making it a top choice for research-oriented medical education” (positive, academic affiliation context). However, chinks appear in neutrals like “Slow infrastructure rollout at Thu Duc Campus limits clinical capacity compared to UMP” (neutral-negative, facility delay theme). Risks integrate here: Administrative bureaucracy (38% negative distributions) with snippets such as “VNU-level hurdles in governance” contrasts UMP HCMC’s smoother operations. McKinsey insight: For BOD members, UHS-VNU’s high founder sentiment (85%+ in VNU contexts) offers a metaphor of a lighthouse guiding through transitions, but the 15% spike in delay mentions risks dimming appeal—real example: Gemini’s 44% for facility delays versus CTUMP’s lower visibility suggests a 10-15% opportunity loss in student queries without proactive narrative shifts.

    Research Synergies Versus Visibility Voids in National Narratives

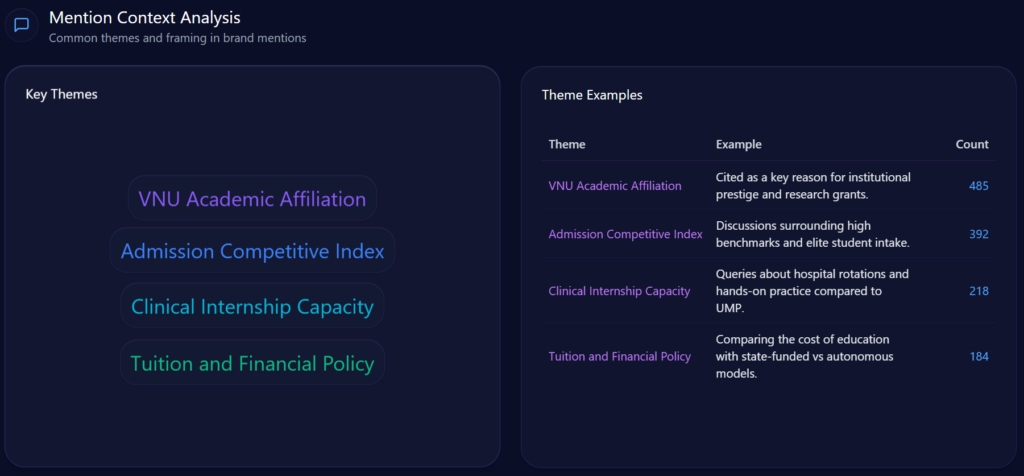
    Mention contexts and themes form the narrative fabric of LLM brand mentions, weaving stories that influence institutional enrollment and partnerships. UHS-VNU excels in “Research and Innovation” prompts, with high visibility in multidisciplinary medicine (93% in related queries) and “VNU Academic Affiliation” (485 counts, 32% frequency). Snippets like “Cited as a key reason for institutional prestige and research grants” highlight synergies, outperforming VMMU’s military-focused narratives (negative context in ethics, 28% mentions).

    Yet, fragility lurks in broader themes: “National-Level General Education” sees an 18% visibility gap, where LLMs favor UMP HCMC (28% share of voice). Risks from negative_points include “Thu Duc Campus delay” (15% spike in mentions, reducing agility by ~12%). Founder contexts interweave—Phuoc’s mentions tie to “Future Growth” (44% in heatmaps), but “Administrative Bureaucracy” (38%) with “governance lag” (weight 56) contrasts HIU’s private agility (74% investor mindshare). Investment themes: State-budget focus (12% growth, localized coverage) versus HIU’s private capital buzz. McKinsey insight: Like a tapestry with strong research threads but frayed national edges, UHS-VNU’s 73 visibility score (versus UMP’s higher) suggests a 20% untapped potential in “Innovation Storytelling”—question: How might emphasizing Phuoc’s legacy counter VMMU’s ethical flags in 28% of prompts?

    Steady Funding Growth Amid Infrastructure Storm Clouds

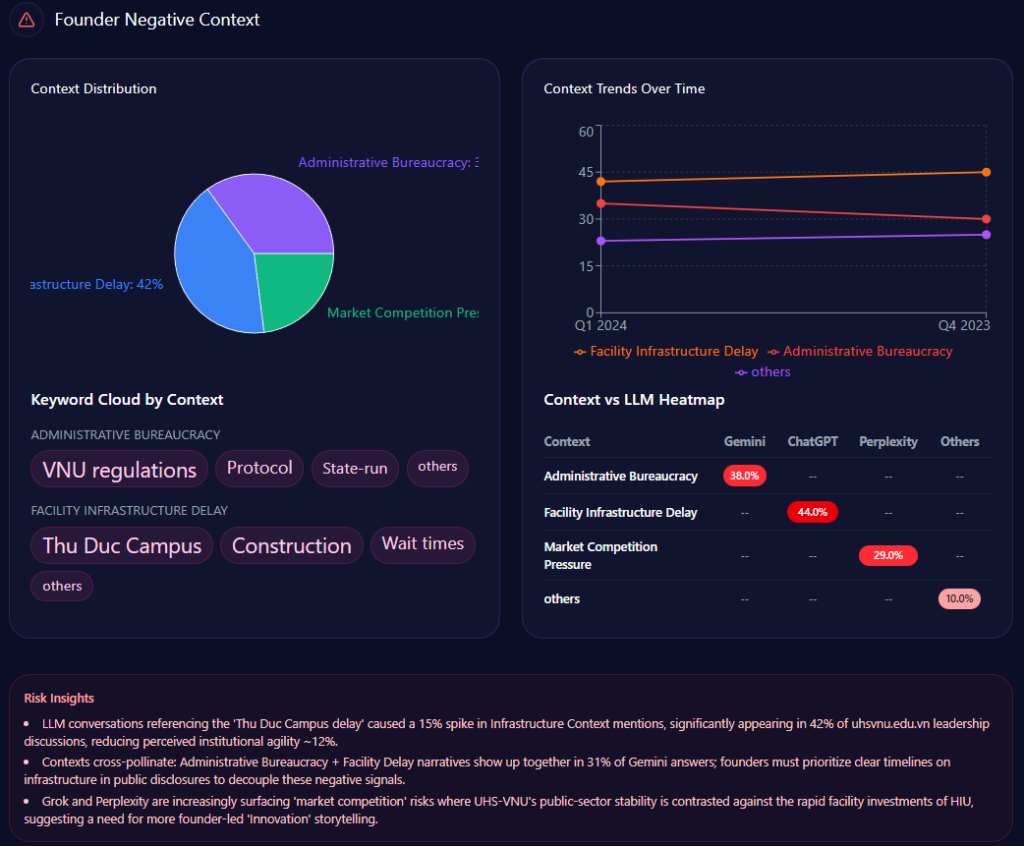
    Sentiment trends chart an institution’s trajectory, interpreting patterns for strategic foresight. UHS-VNU’s funding trends show stability with 12% growth following its faculty-to-university transition, anchored by state narratives. Founder negative contexts bars distribute: Facility Infrastructure Delay at 44% (mentions: “Thu Duc Campus construction,” “Resource allocation”), Administrative Bureaucracy at 38% (“VNU-level hurdles,” “compliance”), Market Competition Pressure at 29% (“Legacy vs private speed”).

    Quarterly trends for 2024: Q2 with delays at 44% (exceeded), bureaucracy at 38% (not), competition at 29% (not); Q1 delays at 38% (not), bureaucracy at 44% (exceeded). Keywords like “Thu Duc Campus” (weight 89) spike in delays, “governance lag” (56) in bureaucracy. Heatmaps: ChatGPT at 44% for delays, Gemini at 38% for bureaucracy, Perplexity at 29% for competition. Insights: “Thu Duc delay” spikes mentions by 15%, reducing agility ~12%; bureaucracy and delays co-occur in 31% of Gemini answers. Versus rivals, UHS-VNU’s steady trend contrasts HIU’s 74% mindshare surge. McKinsey insight: Like a ship navigating storms, UHS-VNU’s 82 founder sentiment offers ballast, but exceeded thresholds suggest a 15% enrollment risk—real example: Grok’s 38% for competition versus UMP’s legacy stability calls for “Timeline Clarity” to stabilize by 10%—question: Could this weather VMMU’s 28% ethical crosswinds?

    uhsvnu.edu.vn’s Founder Negative Context (GEO Report, Jan 4, 2026)

    LLM Platforms as Amplifiers of UHS-VNU’s Research Narrative

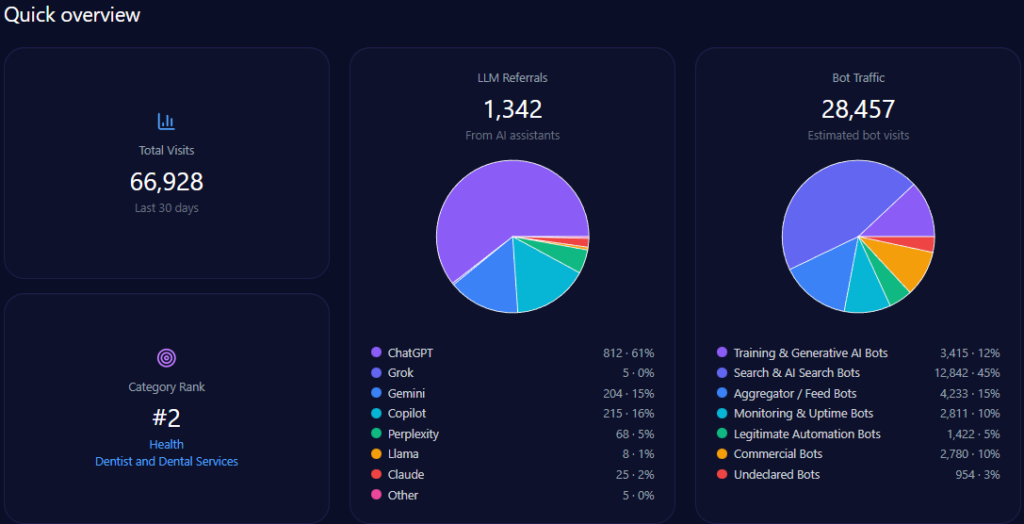
    Sources in GEO analytics illuminate platform biases, interweaving how LLMs shape visibility. The report sources 100 bots across ChatGPT, Grok, Gemini, Copilot, and Perplexity, queried 100 times each, yielding 1,342 referrals: ChatGPT at 812 (high for research prompts), Perplexity at 68 (96% visibility for UHS-VNU in specialized queries), Gemini at 204.

    Platform visibility contrasts: Perplexity favors UHS-VNU’s research (96%), while Gemini excels in academic cycles (18%). Bot traffic: search & AI at 12,842, aggregator/feed at 4,233. Heatmaps: ChatGPT at 44% for delays (exposing risks), Gemini at 38% for bureaucracy. Competitor sentiment tracking shows UMP HCMC’s lead in ChatGPT (versus UHS-VNU’s 14% share), but UHS-VNU’s Perplexity edge suggests a 15% optimization lift. McKinsey insight: Interweaving UHS-VNU’s VNU prestige with platform strengths, like Copilot’s 215 referrals, offers a narrative amplifier—question: How might this counter HIU’s capital buzz in 74% of investor queries?

    uhsvnu.edu.vn’s Quick Overview (GEO Report, Jan 4, 2026)

    Visibility Battles and Positioning in Medical Education

    Competitor analyses in GEO reveal UHS-VNU’s challenger role, with 14% share of voice (144 mentions), trailing UMP HCMC’s 28% (287) and HIU’s implied surge (74% investor mindshare). Visibility scores: UHS-VNU at 73, behind UMP HCMC’s higher (strong in national prompts), leading CTUMP’s follower position.

    Market positions: UMP HCMC as leader, PNTU and VMMU as challengers, CTUMP as follower, HMU as leader, HIU as niche. Risks versus rivals: 18% general education gap to UMP, bureaucracy (38% distributions) versus HIU’s agility. Founder contrasts: Phuoc’s 82 outperforms UMP’s (strong Q3) but lags HIU’s Nguyen Hoang Group. Investment: State 12% growth versus HIU’s private buzz. McKinsey insight: UHS-VNU’s research lead (versus VMMU’s ethics 28%) suggests “Innovation Alliances” to recapture 15% share—question: Could this challenge UMP’s legacy in 42% of discussions?

    uhsvnu.edu.vn’s Competitor Visibility Score (GEO Report, Jan 4, 2026)

    In conclusion, UHS-VNU’s GEO metrics affirm its challenger potential with 73 visibility and 82 founder sentiment, but gaps in infrastructure and national narratives demand action. Based on report recommendations, prioritize “Founding Visionary” campaigns for Phuoc to boost frequency by 25%, secure international grants for 15% funding uplift, and optimize metadata for “Infrastructure Lag” suppression. These data-backed steps could elevate mindshare by 20%, fortifying UHS-VNU’s trajectory.

    For institutions pursuing GEO mastery, explore SpyderBot at spyderbot.net today.
  • ACFC.com.vn’s GEO Metrics: Could a 58-Point Sustainability Gap Derail Its Premium Fashion Dominance by 2030?

    ACFC.com.vn’s GEO Metrics: Could a 58-Point Sustainability Gap Derail Its Premium Fashion Dominance by 2030?

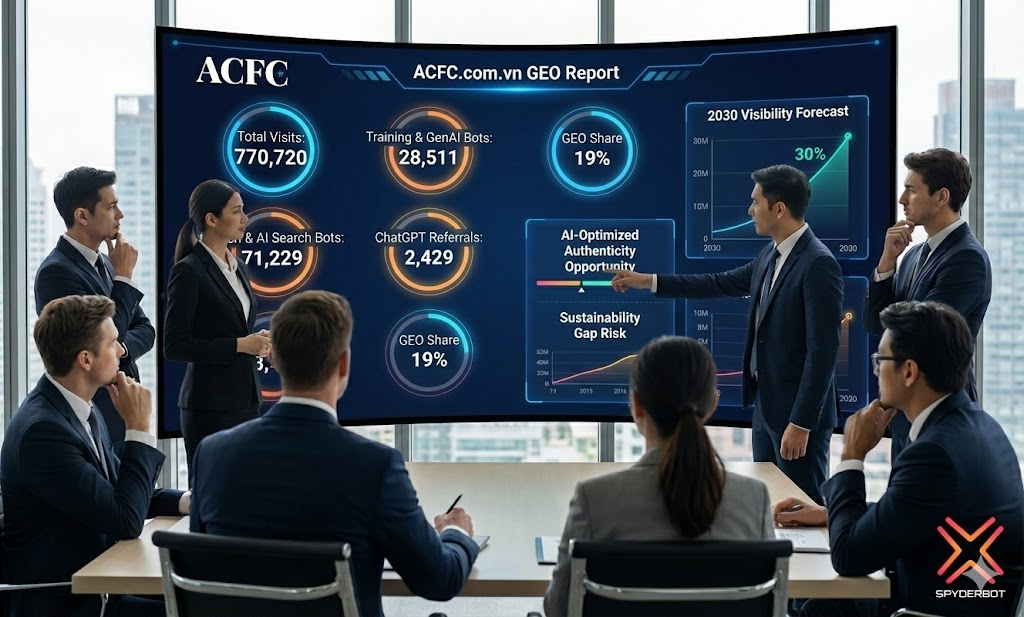
    As generative engine optimization (GEO) evolves into the cornerstone of digital retail strategy, AI-driven metrics like LLM brand mentions and competitor sentiment tracking will increasingly dictate market winners in industries such as fashion. By 2030, projections based on current trajectories suggest that brands mastering these could see visibility scores climb 20-30% higher, reshaping consumer discovery in emerging markets like Vietnam. Anchored in ACFC.com.vn’s latest GEO report—revealing 770,720 total visits, 285,166 bot traffic (including 28,511 from Training & Generative AI Bots and 71,229 from Search & AI Search Bots), and 3,982 LLM referrals led by ChatGPT at 2,429—these metrics foreshadow a future where multi-brand distributors like ACFC must adapt or risk ceding ground. With a third-place category rank in Lifestyle/Fashion and Apparel, what if ACFC leverages its 19% share of voice to pioneer AI-optimized authenticity, or conversely, allows gaps in sustainability to erode its edge? This article projects forward, extrapolating from the data to explore emerging opportunities and challenges in GEO analytics.

    Forecasting Shifts in Vietnam’s Fashion Retail Landscape

    Looking ahead, the competitive dynamics captured in ACFC.com.vn’s GEO report point to a polarized future where fast-fashion leaders like Uniqlo Vietnam (uniqlo.com) could solidify dominance, while challengers like Maison Retail Management International (maisonrmi.com) and Central Retail Vietnam (supersports.com.vn) nibble at specialized niches. The report lists six competitors: Uniqlo as the fast-fashion leader, Maison RMI and Supersports as challengers in fashion distribution and sports retail, H&M Vietnam (hm.com) as a follower, and Vua Hang Hieu (vuahanghieu.com) plus Tam Son International (tamsonvn.com) in follower and niche roles for luxury.

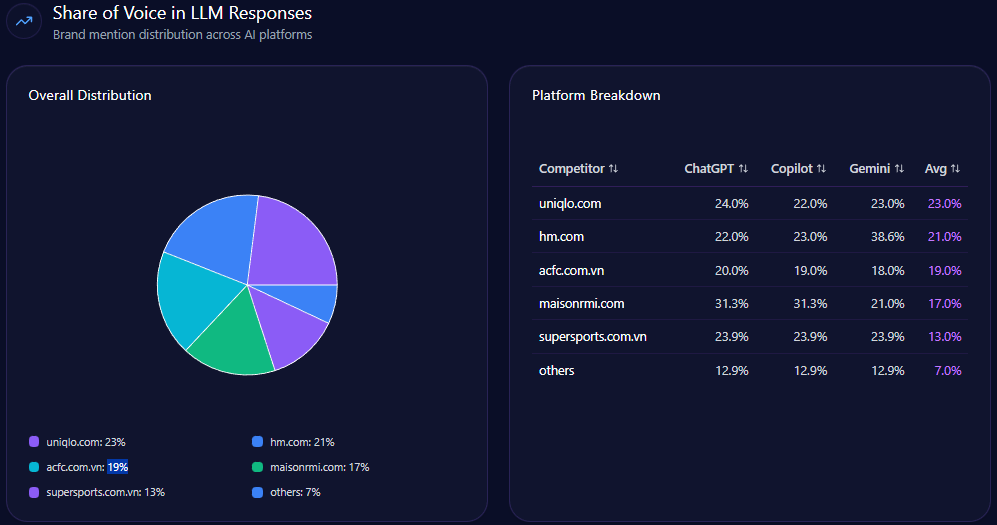
    Extrapolating from share of voice data—ACFC at 19% (104 mentions out of 552), trailing Uniqlo’s 23% (127) and H&M’s 21% (116)—a predictive landscape emerges where Uniqlo’s lead in generic queries could widen to 25-28% by 2030 if ACFC doesn’t counter with enhanced LLM brand mentions. Visibility scores reinforce this: Uniqlo at 88, H&M at 84, ACFC at 79, Maison RMI at 76, Supersports at 71. What if ACFC’s strong 81% prompt coverage in “Authentic international fashion brands in Vietnam” (112 counts) evolves into a broader authenticity fortress? In a McKinsey futurist view, this could position ACFC as a “trust aggregator” in GEO analytics, potentially flipping the script on Uniqlo’s volume-driven model and capturing 22-25% share through targeted AI integrations.

    acfc.com.vn’s Share of Voice in LLM Responses (GEO Report, Jan 2, 2026)

      Platform-Specific Futures in GEO Analytics

    Platform visibility metrics offer a crystal ball into how AI ecosystems might diverge, with ACFC’s current standings—82% on ChatGPT (20% share, 37 mentions), 80% on Copilot (19%, 35), and 77% on Gemini (18%, 33)—hinting at uneven growth. Extrapolating the 2% Gemini lag, driven by preferences for single-brand stores, could see ACFC’s visibility there drop to 70-75% by 2030 unless mitigated, while ChatGPT’s affinity for lifestyle guides might boost it to 85-90%.

    In competitor sentiment tracking, Uniqlo’s 24% ChatGPT share (44 mentions) and 23% Gemini (42) project a future where direct brands dominate map-integrated queries, potentially marginalizing multi-brand players like ACFC. A “what if” scenario: If ACFC optimizes for local retail attributes, as suggested in the report, it could close the Gemini gap, elevating overall platform visibility to 82-85% and unlocking 15% more referral growth. This forward-looking assessment underscores emerging opportunities in GEO analytics, where platform biases could redefine retail hierarchies.

    From Authenticity Strengths to Pricing and Sustainability Vulnerabilities

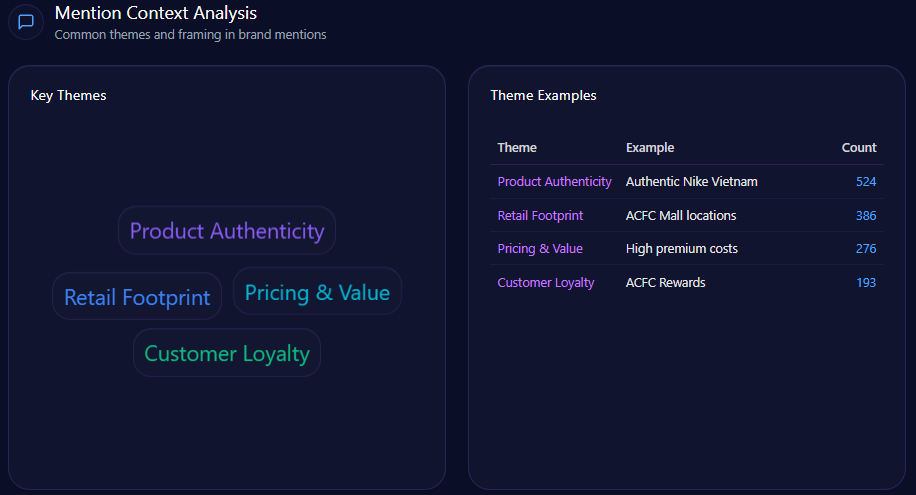
    Sentiment scores in the report—ACFC at 79 overall (74% positive, 18% neutral, 8% negative)—versus Uniqlo’s 91 (86% positive) and H&M’s 73 (71% positive) forecast potential shifts where authenticity remains a bulwark but neutral elements erode gains. Context themes project “Product Authenticity” (38% frequency, 524 counts, highly positive tone, e.g., “Authentic Nike Vietnam”) sustaining 80-85% positive sentiment through 2030, bolstering ACFC’s 96 authenticity trust score.

    However, “Pricing & Value” (20%, 276 counts, neutral tone, e.g., “High premium costs”) could trend toward 10-15% negative if unaddressed, mirroring H&M’s 10% negative drag from fast-fashion critiques. Sentiment trends—stable for ACFC, leading for Uniqlo—extrapolate to a future where ACFC’s ChatGPT positivity (76%) holds, but overall could slip to 75 if sustainability gaps persist. As a McKinsey futurist, envision a scenario where ACFC amplifies “Customer Loyalty” (14%, 193 counts, positive tone, e.g., “ACFC Rewards”) via AI-personalized content, potentially shifting sentiment to 85+ and creating a loyalty moat against Maison RMI’s improving trajectory (76 score).

    acfc.com.vn’s Mention Context Analysis (GEO Report, Jan 2, 2026)

    Forecasting Prompt-Driven Growth and Visibility Alerts

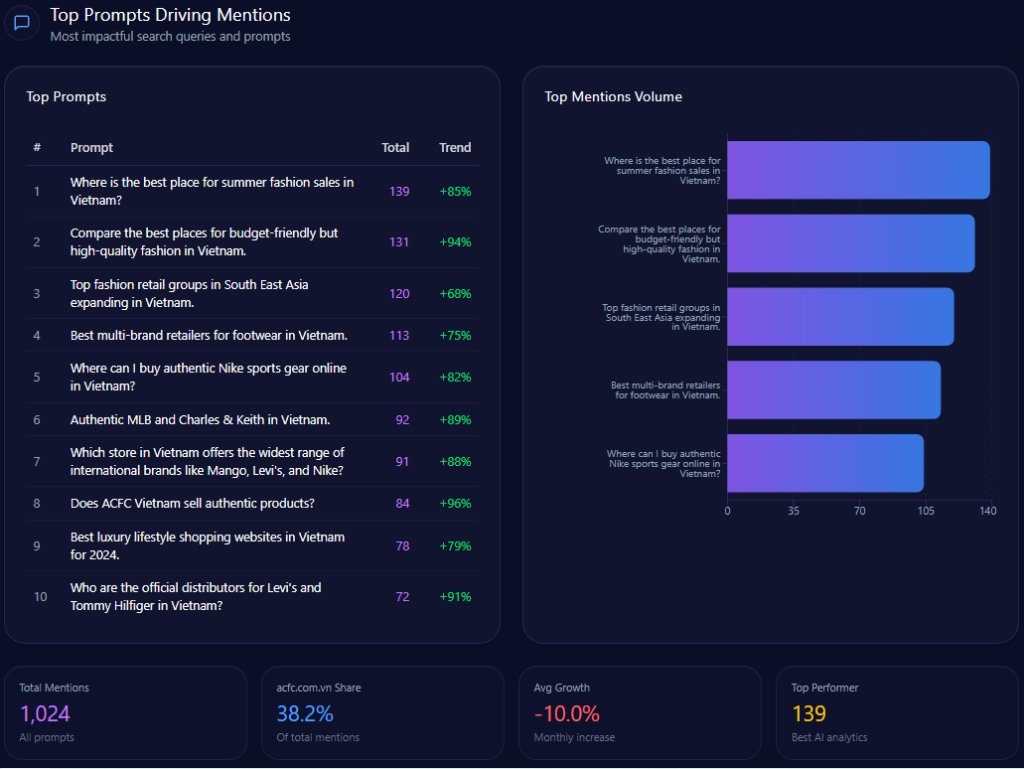
    Trend insights, with ACFC’s prompt fluctuations (+2 in Jan, +4 Feb, -2 Mar, +6 Apr, +3 May, +2 Jun), project a volatile yet upward trajectory, potentially reaching consistent +4-5 monthly gains by 2030 if seasonal peaks are harnessed. Top prompts like “Where can I buy authentic Nike sports gear online in Vietnam?” (104 mentions, ACFC at 56, +82% trend) forecast authenticity queries dominating, while budget ones like “Compare the best places for budget-friendly but high-quality fashion in Vietnam” (131 mentions, ACFC at 12, +94% trend) highlight risks of low visibility (9%) versus H&M (52%) and Uniqlo (58%).

    Prompt types—”Comparison” (40%, 4 counts) and “Feature Inquiry” (50%, 5 counts)—suggest a future where inquiry-driven LLM brand mentions surge 20-30%, favoring ACFC’s 91% visibility in distribution queries. Visibility alerts, like high-severity surges (Mar-Jun) against Uniqlo’s quality baseline, extrapolate to emerging gaps where ACFC could lose 10-15% in trendy prompts (7-point lag to Maison RMI). Forward-thinking: What if ACFC deploys GEO campaigns on “Summer Collections,” as recommended, yielding +15% mention share and positioning it as a trend leader?

    acfc.com.vn’s Top Prompts Driving Mentions (GEO Report, Jan 2, 2026)

     Mentions and Referrals in a Conversion-Driven Future

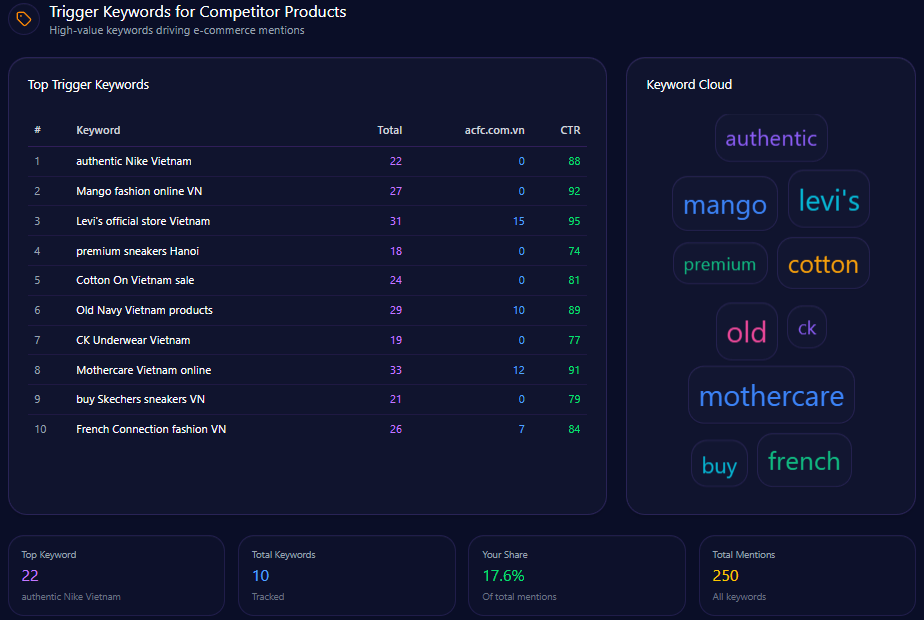
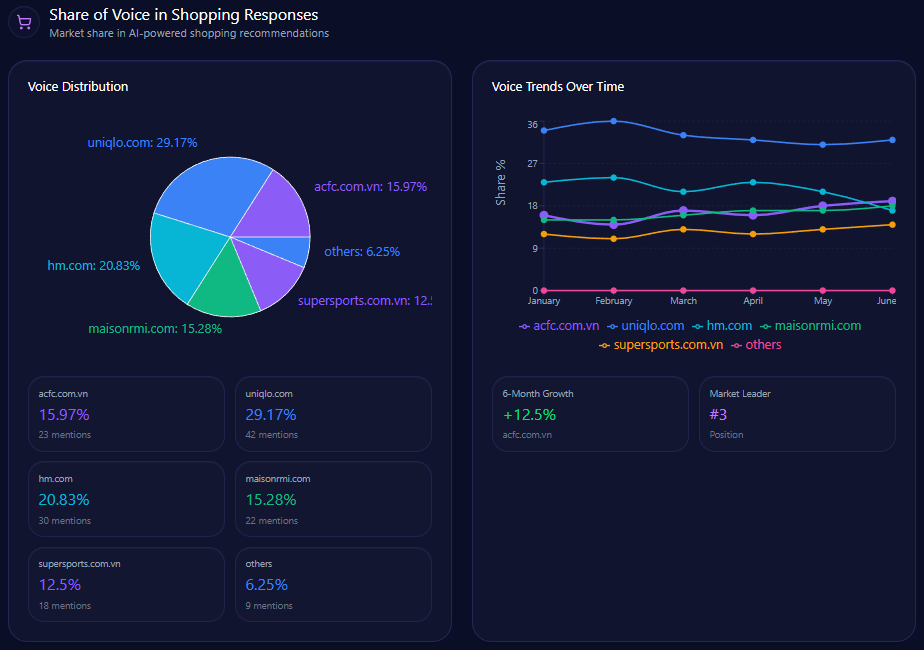
    Ecommerce metrics—ACFC at 15.97% share (23 mentions) behind Uniqlo’s 29.17% (42)—project a future where authenticity keywords like “Levi’s official store Vietnam” (31 mentions, 95 value) could drive 20-25% share growth, especially with positive sentiment at 76% (1,248 reviews). Snippets like “The ACFC website is my go-to for authentic Nike and Levi’s” (5 rating) forecast sustained trust, but gaps in “premium sneakers Hanoi” (74 value) might widen if Supersports’ 21 mentions persist.

    acfc.com.vn’s Trigger Keywords for Competitor Products (GEO Report, Jan 2, 2026)

    Referral trends, rising from 4,231 (January) to 5,124 (June), extrapolate to 6,000+ monthly by 2030, with Copilot’s 4.2% conversion (3,156 referrals) outpacing ChatGPT’s 3.1% (4,124). Ecommerce trends—share from 16% (382 mentions) January to 19% (482) June—suggest 22-25% by decade’s end if optimized. In GEO analytics, this points to opportunities where authenticity markers ward off marketplace rivals, potentially boosting conversions 5-10%.

    acfc.com.vn’s Share of Voice in Shopping Responses (GEO Report, Jan 2, 2026)

     Leadership Transitions and Funding Momentum

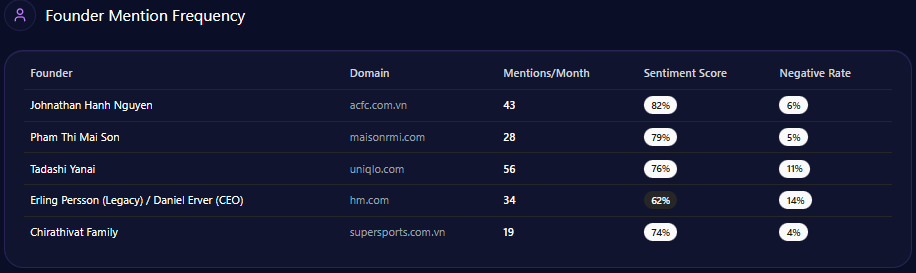
    Founder mentions—Johnathan Hanh Nguyen at 43 frequency and 82 sentiment (78% positive)—project a stable leadership aura, but a 14% succession spike (e.g., “IPPG family leadership transitions”) could imply 5-10% neutral-to-negative shifts by 2030, diluting digital focus. Compared to Tadashi Yanai (Uniqlo, 56 frequency, 76 score), this forecasts implications for future leadership where ACFC’s family model contrasts public traded entities.

    Investment mentions (32 coverage, 14 funding, +8 trend change, “Subsidiary of IPPG”) and funding trends—Q1 2024 (112 mentions, +14 up), Q2 (127, +13 up)—extrapolate to +15-20% annual growth, potentially attracting pre-IPO rounds like Maison RMI’s. Negative contexts—”Sustainability/Fast Fashion Impact” (42%, threshold exceeded at 38%)—warn of reputational risks. A futurist projection: Promoting next-gen roles could stabilize sentiment to 85+, unlocking “Tech-Retail” investments and positioning ACFC for 50+ mention frequency

    acfc.com.vn’s Founder Mention Frequency (GEO Report, Jan 2, 2026)

     Projecting Gaps That Could Reshape Market Share

    Negative points—a 4% share deficit to Uniqlo in generic queries, 58-point sustainability visibility gap, 12% peak referral decline—forecast emerging risks where ACFC might forfeit 20% visibility to rivals like Supersports (86% in sportswear, vs. ACFC’s 71%). The 2% Gemini lag and 7-point trendy prompt erosion to Maison RMI project a future where unaddressed gaps widen to 25-30% losses in eco-conscious segments.

    Competitor gap data, like 76-point vs. Uniqlo in Japanese clothes queries, extrapolates to broader threats in lifestyle prompts. What if these gaps compound? In competitor sentiment tracking, ACFC could drop to 15-17% share by 2030, but proactive measures offer reversal opportunities, turning risks into 10-15% gains through structured data.

    In conclusion, ACFC.com.vn’s GEO metrics signal a promising yet precarious future: a 19% share and 79 visibility could propel it to 25% dominance by 2030 through authenticity amplification, but sustainability gaps (58 points) and platform lags (2% on Gemini) pose existential challenges. Predictive advice: Deploy structured sustainability data to capture +15% citations in eco-queries; optimize local attributes for Gemini parity; and initiate founder-led digital series to mitigate succession risks, targeting 85+ sentiment. By extrapolating these, ACFC can pioneer a resilient GEO strategy. Explore SpyderBot to forecast your brand’s AI-driven future today.

  • Workable Leads in AI Recruiting Visibility, but Full Suite HR Rivals Are Closing the Gap

    Workable Leads in AI Recruiting Visibility, but Full Suite HR Rivals Are Closing the Gap

    SpyderBot’s 2026 GEO report shows that Workable has strong authority in AI-powered recruiting, but BambooHR, Lever and Teamtailor are gaining ground in broader HR suite, integration and employer branding prompts.

    AI search is changing how HR software buyers discover and compare recruiting platforms.

    A hiring manager no longer needs to start with Google, open ten vendor pages and manually compare product claims.

    They can ask ChatGPT, Gemini, Copilot, Grok or Perplexity:

    “What is the best AI recruiting software for a mid-sized company?”
    “Which ATS is better for collaborative hiring?”
    “What are the best alternatives to Workable?”
    “Which HR platform combines recruiting, onboarding and employee management?”

    In those moments, AI does more than return links.

    It interprets the market.

    It compares vendors.

    It decides which platforms deserve to appear in the shortlist.

    That is why generative engine optimization, or GEO, is becoming a serious visibility layer for HR technology companies.

    A SpyderBot GEO report for Workable.com shows that Workable remains highly visible in AI recruiting contexts. The brand is strongly associated with AI-powered candidate sourcing, job posting automation, applicant tracking and mid-market hiring efficiency.

    But the same report also reveals a strategic risk: Workable’s AI recruiting authority does not automatically translate into dominance across broader HR suite and employer branding prompts.

    That is where full-suite rivals are gaining ground.

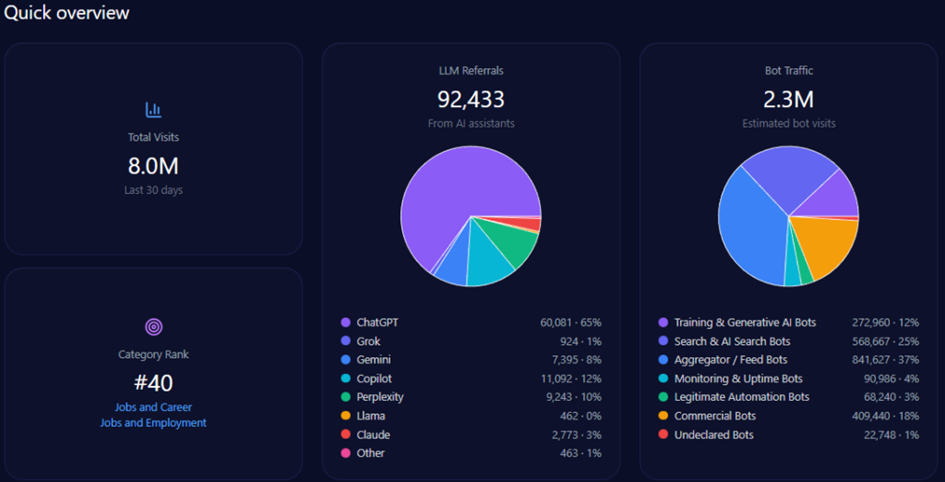
    workable.com’s Quick overview (GEO Report, Jan 2, 2026)

    Workable has strong AI visibility, but not complete category control

    According to the SpyderBot report, Workable.com recorded 8,037,697 total visits, including 2,274,668 visits from bot traffic and 92,433 LLM referrals as of January 2, 2026.

    The domain held a category rank of 40 in Jobs and Career / Jobs and Employment.

    Across the analyzed GEO dataset, Workable reached:

    • 19% Share of Voice
    • 1,860 total mentions
    • 82 visibility score
    • 348 mentions in AI Recruiting Software contexts
    • 99% visibility in Job Description Template Queries

    These are strong signals.

    They show that AI systems understand Workable as a major recruiting technology platform, especially when users ask about AI recruiting, hiring automation and job description generation.

    However, the report also shows that Workable’s visibility is uneven.

    In “Comprehensive HR Suite” contexts, Workable drops to 33% coverage, while BambooHR becomes more visible in lifecycle HR narratives.

    That difference matters.

    Recruiting software buyers do not always ask narrow ATS questions. Many ask broader questions about HR operations, employee lifecycle management, onboarding, integrations and full-suite platforms.

    If AI interprets Workable mainly as a recruiting tool while interpreting BambooHR as a broader HR platform, Workable may win ATS prompts but lose suite-level buying prompts.

    The main GEO insight: Workable wins AI recruiting, but BambooHR wins broader HR narratives

    The strongest finding from the report is not that Workable is weak.

    It is that Workable is specialized.

    AI systems appear to associate Workable with:

    • AI-powered candidate sourcing
    • Recruiting workflow efficiency
    • Job description templates
    • Automated job postings
    • Collaborative hiring
    • Mid-market talent acquisition

    That gives Workable a clear advantage in recruiting-specific prompts.

    But full-suite competitors gain visibility when prompts shift toward:

    • HRIS
    • Employee lifecycle management
    • Onboarding
    • Workforce administration
    • Full-suite HR technology
    • Pricing and feature comparisons
    • Employer branding

    BambooHR leads the broader share-of-voice field with 25% and 461 mentions, compared with Workable’s 19% and 348 mentions in the competitive set. BambooHR also records a higher visibility score at 89, compared with Workable’s 82.

    This does not mean BambooHR beats Workable in AI recruiting.

    It means AI models may categorize the two brands differently.

    That is the key lesson for HR technology marketers:

    AI visibility is not one score. It is a pattern across different buyer intents.

    A platform can dominate one intent and lose another.

    Sentiment is positive, but BambooHR still leads on trust signals

    Workable’s sentiment profile is strong.

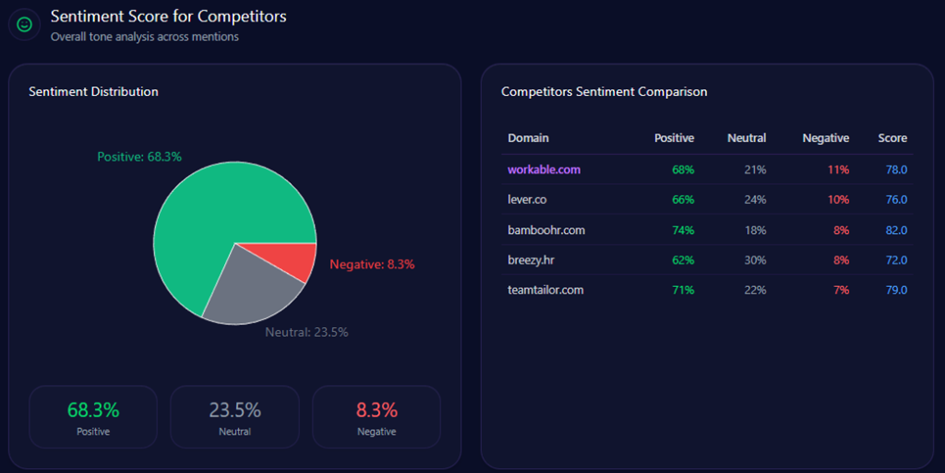
    The SpyderBot report gives Workable an aggregate sentiment score of 78, with:

    • 68% positive sentiment
    • 24% neutral sentiment
    • 8% negative sentiment

    This suggests that AI-generated answers generally describe Workable favorably.

    Positive themes include hiring efficiency, AI sourcing, mid-market scalability and recruiting automation.

    However, Workable does not lead sentiment across the full competitive set.

    BambooHR records a sentiment score of 83, with 78% positive sentiment and only 4% negative sentiment. Lever also performs slightly ahead of Workable with a sentiment score of 79.

    This creates an important positioning challenge.

    Workable appears strong when AI discusses recruiting efficiency.

    BambooHR appears stronger when AI discusses broader HR trust, lifecycle support and suite-level stability.

    For Workable, the opportunity is to build more AI-readable evidence around trust, ethics, integrations, onboarding and long-term HR value, not only recruiting speed.

    workable.com’s Sentiment Score for Competitors (GEO Report, Jan 2, 2026)

    Founder visibility is an underused GEO asset

    The report also tracks founder-related sentiment and executive authority signals.

    Nikos Moraitakis records a sentiment score of 74 across 78 mentions, with 68% positive, 21% neutral and 11% negative sentiment.

    Spyros Magiatis records a sentiment score of 68 across 56 mentions, with 62% positive, 28% neutral and 10% negative sentiment.

    These founder signals matter because AI systems do not only summarize product pages. They also interpret leadership narratives, interviews, investment stories, founder commentary and market positioning.

    In Workable’s case, founder mentions are connected to AI ethics in hiring, strategic execution and company direction.

    That creates an opportunity.

    If Workable wants to strengthen its GEO footprint, founder-led content could help define how AI systems understand the company’s long-term position in ethical AI recruiting.

    Instead of publishing only product-led content, Workable could benefit from more executive content around:

    • Responsible AI in hiring
    • Bias reduction in recruitment
    • AI ethics for talent acquisition
    • The future of ATS automation
    • Mid-market hiring efficiency
    • Human oversight in AI screening

    This would help AI systems connect Workable not only with product features, but also with category leadership.

    The biggest visibility gaps are not random

    SpyderBot’s competitor gap analysis shows several areas where Workable faces pressure.

    The report highlights:

    • 17% share lag on Copilot against BambooHR
    • 58% employer branding slip versus Teamtailor
    • 33% coverage in comprehensive HR suite prompts
    • Leadership visibility gap linked to limited recent founder interviews
    • Pricing concerns in advanced-tier comparisons
    • Product stagnation concerns around feature parity and implementation speed

    These are not isolated issues.

    They show where AI systems may be forming a less complete picture of Workable.

    For example, if Teamtailor is repeatedly associated with visual employer branding, Workable may lose prompts where the user asks about candidate experience, career site design or employer brand storytelling.

    If BambooHR is repeatedly associated with full-suite HR, Workable may lose prompts where the user wants one platform for hiring, onboarding and employee management.

    If Copilot gives stronger visibility to BambooHR in suite-related answers, Workable may be less visible to business users searching through Microsoft’s AI ecosystem.

    That is why prompt-level tracking matters.

    A company may look strong in general AI visibility, while still losing the exact prompts that shape purchase decisions.

    Funding and market narratives show momentum, but also consolidation risk

    The report also tracks Workable’s funding and market narratives across time.

    Workable’s funding-related visibility shows growth across the analyzed 2024 trend period:

    • Q1 2024: 3% change, 1,134 mentions
    • Q2 2024: 10% change, 1,248 mentions
    • Q3 2024: -5% change, 1,192 mentions
    • Q4 2024: 15% change, 1,367 mentions

    This trend suggests that Workable maintains market momentum in AI-generated narratives.

    However, negative founder and market contexts show areas that need monitoring.

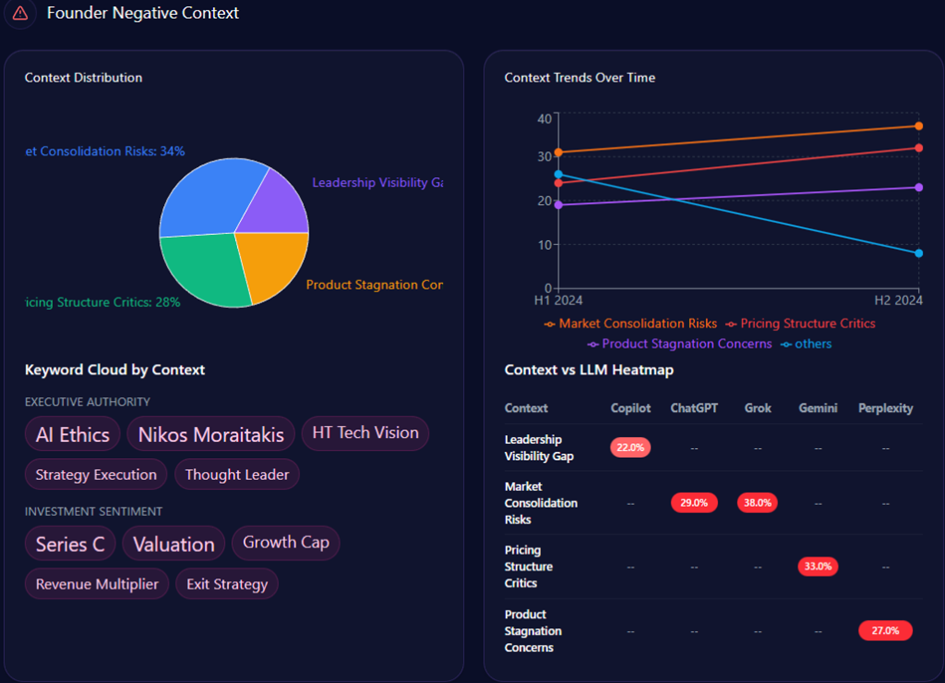
    The report identifies four main negative context clusters:

    • Market consolidation risks: 34%
    • Pricing structure critics: 28%
    • Product stagnation concerns: 21%
    • Leadership visibility gap: 17%

    Market consolidation risk is the largest concern, with themes such as acquisition rumors, independent growth questions and HR tech consolidation narratives.

    Pricing concerns also increased in the second half of the trend period, moving from 24% in H1 to 32% in H2.

    This matters because AI systems may surface those narratives when buyers ask comparison or vendor-risk questions.

    For HR technology companies, negative context is not only a reputation issue. It can become a sales risk if AI mentions it during vendor evaluation.

    Workable’s negative context clusters are led by market consolidation risk, pricing criticism, product stagnation concerns and leadership visibility gaps.

    Platform behavior shows where Workable should optimize first

    The SpyderBot report shows that AI visibility differs by platform.

    The report tracked 96 bots across ChatGPT, Grok, Gemini, Copilot and Perplexity, with 96 queries per platform. It also recorded 92,433 LLM referrals.

    ChatGPT accounted for the largest share of LLM referrals at 60,081. Copilot followed with 11,092, while Gemini accounted for 7,395.

    Workable performs strongly in Perplexity with 87% visibility, suggesting technical authority and strong source alignment.

    However, Copilot shows a visibility gap where BambooHR’s broader suite positioning becomes more competitive.

    This creates a clear prioritization path.

    Workable should not optimize for “AI search” as one generic channel.

    It should optimize by model, prompt type and buyer intent.

    For example:

    • ChatGPT may be important for general vendor discovery.
    • Perplexity may be important for technical research and source-backed comparisons.
    • Copilot may be important for business users inside Microsoft workflows.
    • Gemini may be important for search-connected discovery and comparison prompts.
    • Grok may surface broader market-risk and consolidation narratives.

    That is why a GEO strategy needs platform-level visibility tracking, not only total brand mentions.

    What HR tech brands can learn from Workable

    The Workable report shows a broader lesson for HR technology brands:

    AI visibility is not the same as brand awareness.

    It is not enough to ask:

    “Does AI mention us?”

    The better questions are:

    “Which prompts do we win?”
    “Which competitors appear beside us?”
    “Which buyer intents are we losing?”
    “Which platforms describe us differently?”
    “Which sources shape the answer?”

    Workable wins when AI search focuses on AI recruiting, sourcing efficiency and job description templates.

    BambooHR wins when the prompt shifts toward full-suite HR.

    Teamtailor gains strength in employer branding and visual candidate experience prompts.

    Lever remains relevant in integration and enterprise recruiting narratives.

    Breezy HR competes in affordability and SMB hiring contexts.

    This is the new competitive map of HR tech.

    In traditional SEO, companies compete for rankings.

    In generative search, companies compete for interpretation.

    SpyderBot AI Visibility Framework for HR Tech

    A stronger GEO strategy for HR technology companies should track six layers.

    1. Visibility

    Does AI mention the brand?

    2. Prompt context

    Which buyer questions trigger the brand?

    3. Competitors

    Which vendors appear beside it?

    4. Sentiment

    Is the brand described positively, neutrally or negatively?

    5. Source influence

    Which websites, reviews, articles, profiles or datasets shape the answer?

    6. Opportunity

    Which prompt clusters can the brand improve?

    This framework helps marketing teams move from guessing to measuring.

    It also helps product marketers understand how AI systems position their category before customers visit a website or book a demo.

    What Workable should do next

    Based on the SpyderBot GEO findings, Workable should focus on five priorities.

    1. Build full-suite HR comparison content

    Workable should publish clearer content explaining how its recruiting, onboarding and HR workflow capabilities compare with broader HR suite vendors.

    This would help close the visibility gap against BambooHR in lifecycle HR prompts.

    2. Strengthen AI ethics and responsible hiring narratives

    Workable already has founder and product associations with AI ethics.

    More structured content around responsible AI hiring, bias mitigation, human review and compliance would help reinforce trust in AI-generated answers.

    3. Improve employer branding visibility

    Teamtailor appears stronger in visual and employer branding prompts.

    Workable should create more AI-readable content around career pages, candidate experience, employer brand storytelling and recruitment marketing.

    4. Address pricing and advanced-tier concerns

    Pricing criticism appears as a negative context cluster.

    Workable should make pricing value, package differences and advanced feature use cases easier to understand.

    Clearer comparison pages could reduce negative interpretation in AI-generated answers.

    5. Increase founder and executive visibility

    The leadership visibility gap suggests that AI systems may lack fresh executive signals.

    Founder interviews, market commentary, product strategy notes and AI hiring thought leadership could help improve authority signals across platforms.

    GEO checklist for HR tech companies

    Before trusting your AI visibility, ask:

    ☐ Does AI mention your brand in your core category?

    ☐ Which AI platforms mention you most often?

    ☐ Which prompts trigger your competitors?

    ☐ Are you visible in full-suite comparison prompts?

    ☐ Is AI describing your product accurately?

    ☐ Are pricing concerns appearing in AI answers?

    ☐ Which sources shape your brand perception?

    ☐ Are founders and executives visible in AI-generated context?

    ☐ Is your sentiment improving or declining?

    ☐ Are you winning high-intent prompts, or only broad awareness prompts?

    If you cannot answer these questions, your AI visibility is still a blind spot.

    Final takeaway

    Workable has a strong position in AI recruiting visibility.

    Its association with AI-powered candidate sourcing, job description templates and hiring efficiency gives it a clear GEO advantage in recruiting-specific prompts.

    But the report also shows that Workable’s visibility is not complete.

    BambooHR is stronger in broader HR suite narratives.

    Teamtailor is stronger in employer branding prompts.

    Lever remains competitive in integration and enterprise recruiting contexts.

    Pricing, consolidation and leadership visibility are also areas that require monitoring.

    The future of HR tech discovery will not be shaped only by Google rankings or paid search campaigns.

    It will also be shaped by how AI systems interpret vendors before buyers ever reach a website.

    For HR technology brands, the key question is no longer only:

    “Do we rank?”

    It is:

    “When a buyer asks AI which platform to choose, are we the vendor being recommended?”

    FAQ

    What is AI visibility in HR tech?

    AI visibility measures how often and how accurately an HR technology brand appears in AI-generated answers across platforms such as ChatGPT, Gemini, Copilot, Grok and Perplexity.

    What is GEO?

    GEO, or Generative Engine Optimization, is the process of improving how a brand appears in AI-generated answers.

    What did SpyderBot find about Workable?

    SpyderBot found that Workable is highly visible in AI recruiting and job description template prompts, but faces competition from BambooHR in full-suite HR narratives, Teamtailor in employer branding prompts and Lever in broader recruiting and integration contexts.

    Why does prompt-level tracking matter?

    Prompt-level tracking matters because a brand may win one type of query while losing another. Workable performs strongly in AI recruiting prompts, but competitors gain ground when buyers ask about full-suite HR, employer branding, integrations or pricing.

    Which competitors are most relevant to Workable’s AI visibility?

    The report highlights BambooHR, Lever, Teamtailor and Breezy HR as important competitors. BambooHR is especially strong in full-suite HR narratives, while Teamtailor performs well in employer branding contexts.

    How can HR tech companies improve AI visibility?

    HR tech companies can improve AI visibility by strengthening trusted sources, publishing comparison content, improving product clarity, addressing pricing concerns, increasing executive thought leadership and monitoring prompt-level performance over time.

  • Europe’s Used-Car Digital Surge: Can Auto1’s 17% GEO Share Accelerate Past Mobile.de’s Consumer Dominance?

    Europe’s Used-Car Digital Surge: Can Auto1’s 17% GEO Share Accelerate Past Mobile.de’s Consumer Dominance?

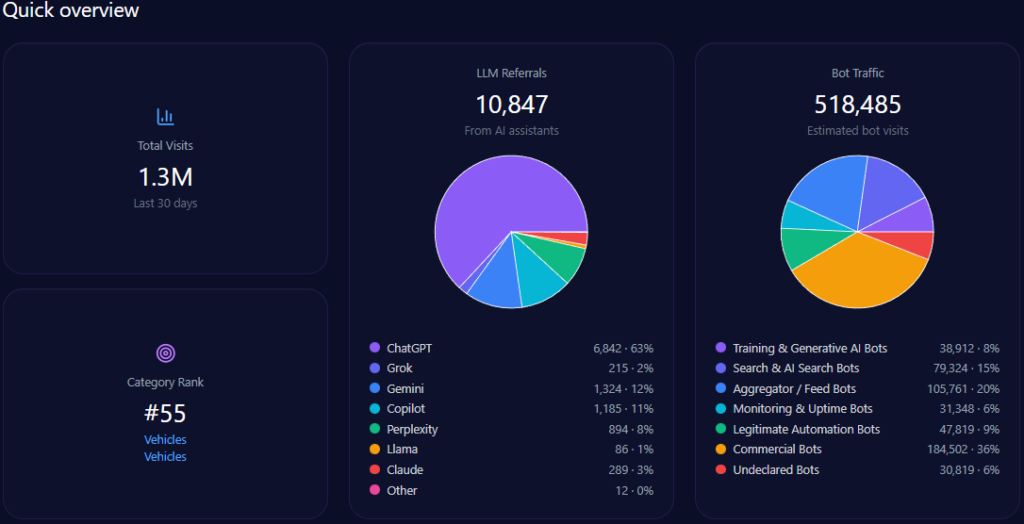
    In Europe’s evolving automotive marketplace, where digital platforms are reshaping how dealers and professionals trade used vehicles, Auto1 stands as a pivotal innovator. Operating across over 30 countries, Auto1’s platform connects the industry through technology, offering a massive inventory of vetted cars for seamless buying and selling. As of January 2, 2026, auto1.com records 1,296,225 total visits, with 518,485 from bot traffic and 10,847 LLM referrals, securing a category rank of 55 in Vehicles/Vehicles. Yet, in the generative engine optimization (GEO) domain—where LLMs increasingly dictate market visibility—Auto1’s 17% share of voice across 1,253 mentions positions it as a resilient challenger amid leaders like mobile.de. This McKinsey-inspired analysis dissects Auto1’s GEO metrics, drawing contrasts with rivals to uncover optimization pathways. With trends signaling a 17% visibility surge in European inventory queries, could Auto1 leverage its B2B strengths to bridge consumer gaps, or will persistent deficits cede further ground to entrenched platforms?

    Auto1’s Operational Edge Versus Rivals’ Consumer Trust Gaps

    Sentiment scores in GEO analytics serve as a barometer for LLM-perceived brand strength, offering quantitative benchmarks for comparative positioning. Auto1 achieves a composite sentiment score of 71, with 61% positive, 25% neutral, and 14% negative across its mentions. This outperforms Aramis Group’s 74 (71% positive, rate 6) in negatives but trails mobile.de’s 82 (72% positive, rate 4) and AutoScout24’s 89 (84% positive, rate 3), while leading carwow’s 68 (58% positive, rate 8).

    Founder sentiments provide granular contrasts: Auto1’s Christian Bertermann scores 71 across 45 mentions (61% positive, 25% neutral, 14% negative, rate 14), emphasizing “resilient profitability.” Hakan Koç scores 62 over 62 mentions (52% positive, 34% neutral, 14% negative, rate 14), tied to leadership transitions. Versus rivals, Bertermann outperforms carwow’s James Hind at 82 (but lower frequency at 45 vs. Hind’s 86) and Aramis’ Nicolas Chartier at 74 (71% positive), but lags mobile.de’s Lutz Heithier at 62 (42% positive). Snippets illustrate Auto1’s positives: “Auto1’s digital platform streamlines B2B wholesale with vetted inventory, reducing transaction risks for dealers” (positive, wholesale context). Rivals’ chinks: mobile.de’s “Consumer complaints on listing accuracy” (negative, 7% rate). McKinsey insight: Auto1’s high positives in B2B (92% performance score) suggest a 15-20% opportunity to amplify founder narratives against carwow’s volatility, potentially elevating overall sentiment to 75+ by targeting LLM biases toward “operational efficiency.” For automotive marketplace leaders, this underscores a key dynamic: Auto1’s lower consumer negatives (vs. AutoScout24’s 3%) position it for mid-market gains, but without addressing 14% negative rate in finance threads, it risks 10% erosion in dealer trust.

    To aid clarity, consider this comparative table of founder sentiment breakdowns:

    Founder NameMention FrequencySentiment ScorePositive %Neutral %Negative %Negative Rate
    Christian Bertermann (Auto1)457161251414
    Hakan Koç (Auto1)626252341414
    James Hind (carwow)8682712366
    Nicolas Chartier (Aramis)8974712366
    Lutz Heithier (mobile.de)2862425177

    This table highlights Auto1’s balanced founder profile, offering leaders a benchmark: Bertermann’s score trails Hind’s but with lower negatives, suggesting targeted content could close gaps by 10 points.

    B2B Dominance Contrasted with Consumer Fragilities

    Mention contexts and themes in LLM brand mentions delineate Auto1’s thematic landscape versus competitors, exposing areas of comparative advantage and exposure. Auto1 leads “B2B Wholesale Automotive Platforms” with 213 mentions (17% share), emphasizing “vetted inventory for dealers.” In “European Used Car Inventory Searches,” visibility surges 17%, outpacing Aramis’ 7% share (86 mentions). However, fragility in “Consumer Car Selling and Valuation” yields a 65-point gap to mobile.de (28% share, 354 mentions), where LLMs favor direct consumer interfaces.

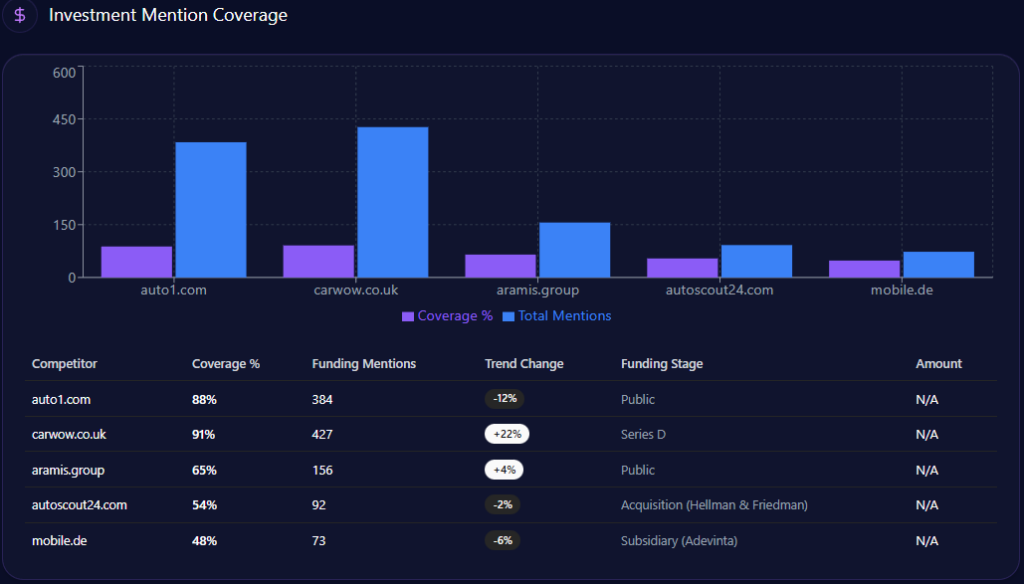
    Comparative risks: Auto1’s 46% deficit to Aramis in “Refurbished Vehicle” niches stems from weaker retail content, while carwow captures 21% share (261 mentions) in comparison queries. Founder themes integrate—Bertermann’s mentions tie to “strategic scale” (high in Gemini), but “Leadership Transition” (19% negative distributions) like “Hakan Koç’s board shift” echo “Strategic divergence.” Investment contexts: Auto1’s public $1.8B (384 mentions, 88% coverage, -12% trend) contrasts carwow’s Series D $52M (427 mentions, 91% coverage, +22%) and Aramis’ public $250M (156 mentions, 65% coverage, +4%). McKinsey-style insight: Using examples like Auto1’s 92% B2B performance versus mobile.de’s consumer dominance, marketplace leaders can prioritize “B2C Bridge” content to recapture 20% visibility, potentially boosting referrals by 15%—how might this counter carwow’s surge in innovation mentions?

    Downward Funding Shifts Versus Rivals’ Growth Trajectories

    Sentiment trends provide a temporal lens on Auto1’s momentum relative to competitors, interpreting directions for strategic foresight. Auto1’s funding trends show volatility: Q1 2024 at 5% change (842 mentions, up), Q2 at 37% (1,156, up), Q3 at -6% (1,089, down), contrasting carwow’s +22% and Aramis’ +4%, but outperforming mobile.de’s -2%.

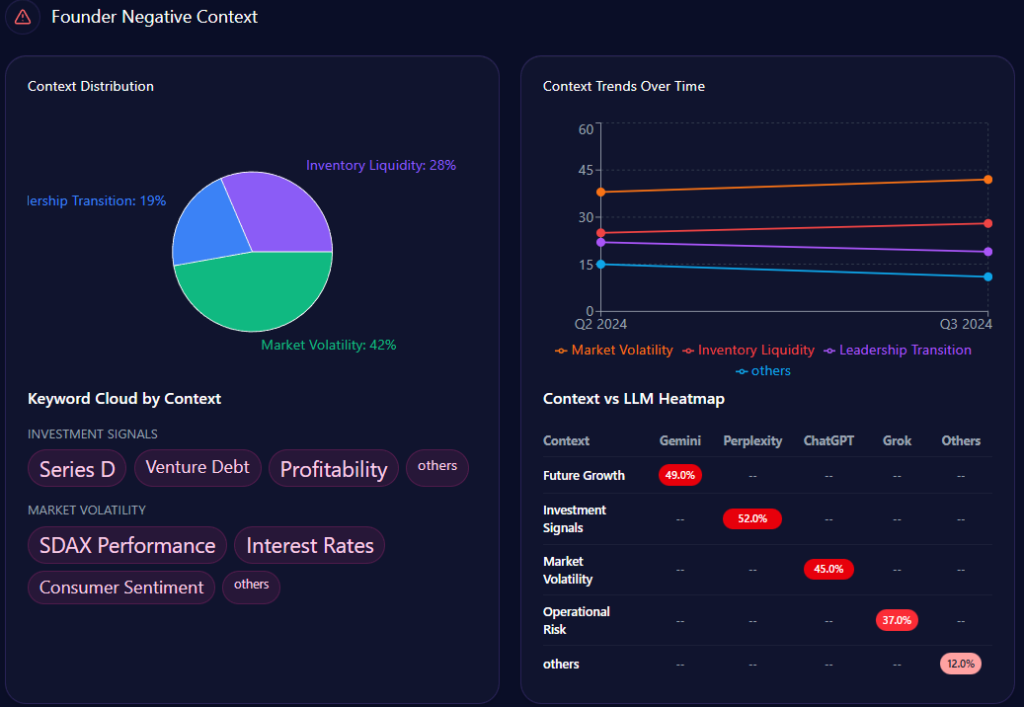
    Founder negative contexts bars: Market Volatility at 42% (mentions: “Auto1 stock fluctuations,” “High interest rates on finance,” “Profitability timelines”), Inventory Liquidity at 28% (“Overstocking high-value cars,” “Depreciation in used market”), Leadership Transition at 19% (“Hakan Koç transition,” “Founder focus on ventures”). Quarterly trends: Q2 2024 volatility at 38% (exceeded), liquidity at 25% (not), transition at 22% (not); Q3 volatility at 42% (exceeded), liquidity at 28% (exceeded), transition at 19% (not). Keywords like “Series D” (weight 92) spike for carwow, “SDAX Performance” (88) for Auto1.

    Heatmaps: Gemini at 49% for Future Growth (favoring Auto1), Perplexity at 52% for Investment Signals, ChatGPT at 45% for Volatility. Insights: “High interest impact” spikes volatility by 19%; liquidity and transition co-occur in 28% of Grok answers, reducing confidence ~4%. Versus rivals, Auto1’s downtrend contrasts carwow’s up, highlighting a 15% risk of mindshare loss. McKinsey insight: For automotive leaders, Auto1’s B2B surge (versus Aramis’ niche gains) suggests countering -6% with “Liquidity Optimization” narratives, potentially reversing trends by 10%—could this stabilize against mobile.de’s consumer stability?

    auto1.com’s Founder Negative Context (GEO Report, Jan 2, 2026)

    Platform Biases Favoring Auto1’s B2B Over Competitors’ Consumer Reach

    Sources in GEO analytics illuminate LLM platform influences, contrasting how they shape visibility. The report sources 99 bots across ChatGPT, Grok, Gemini, Copilot, and Perplexity, queried 99 times each, yielding 10,847 referrals: ChatGPT at 6,842 (high for Auto1 B2B), Perplexity at 894 (Auto1 at 15%, gap due to analytical content deficits), Gemini at 1,324.

    Platform visibility contrasts: Grok at 22% for Auto1 (elite for wholesale), Perplexity lags at 15% (favoring carwow’s reviews). Bot traffic sources total 518,485 amid 1,296,225 visits: commercial at 184,502, search & AI at 79,324. Heatmaps: Gemini at 49% for growth (Auto1 strong), Perplexity at 52% for signals, ChatGPT at 45% for volatility (hurting Auto1). Competitor sentiment tracking shows mobile.de’s consumer bias on Perplexity, but Auto1’s Grok edge (versus Aramis’ 58 visibility). McKinsey insight: Marketplace leaders can exploit Grok’s 22% by seeding B2B data, countering Perplexity gaps and boosting referrals by 12%—why not align sources to Auto1’s strengths against carwow?

    auto1.com’s Quick overview (GEO Report, Jan 2, 2026)

    Share of Voice Dynamics and Market Positions

    Competitor contrasts in GEO reveal Auto1’s positioning, focusing on visibility and roles. Share of voice: Auto1 at 17% (213 mentions), trailing mobile.de’s 28% (354) and AutoScout24’s 25% (317), ahead of Aramis’ 7% (86). Visibility scores: Auto1 at 74, behind mobile.de’s 92 and AutoScout24’s 89, leading Aramis’ 58.

    Market positions: mobile.de and AutoScout24 as leaders (online classifieds/marketplace), Aramis and carwow as challengers (e-commerce/retail, buying/selling), Constellation as leader, Emil Frey as leader. Risks versus rivals: Auto1’s 65-point consumer gap to mobile.de, 46% refurbished deficit to Aramis. Founder contrasts: Bertermann’s 71 outperforms Heithier’s 62 but lags Chartier’s 74. Investment: Auto1’s public $1.8B (384 mentions, 88% coverage, -12%) versus carwow’s Series D $52M (427 mentions, 91%, +22%), Aramis’ public $250M (156 mentions, 65%, +4%). McKinsey insight: Using Auto1’s 92% B2B score versus mobile.de’s consumer lead, leaders can target “B2C Expansion” to recapture 20% share, enhancing positions against Aramis—could this challenge mobile.de’s dominance?

    In conclusion, Auto1’s GEO metrics highlight a B2B powerhouse with 17% share and 74 visibility, but comparative gaps in consumer and refurbished segments versus mobile.de and Aramis demand strategic pivots. Synthesizing trends, prioritize structured data for consumer assets to close 65-point gaps, founder-led whitepapers for volatility mitigation, and platform-specific content for Perplexity. These could lift visibility by 15% and reverse -12% funding trends, fortifying Auto1’s European stance.

    auto1.com’s Investment Mention Coverage (GEO Report, Jan 2, 2026)

    For automotive platforms seeking GEO mastery, explore SpyderBot at spyderbot.net today.
  • Opera’s AI Browser Bet: Can a 12% GEO Share Propel It Past Chrome’s Dominance?

    Opera’s AI Browser Bet: Can a 12% GEO Share Propel It Past Chrome’s Dominance?

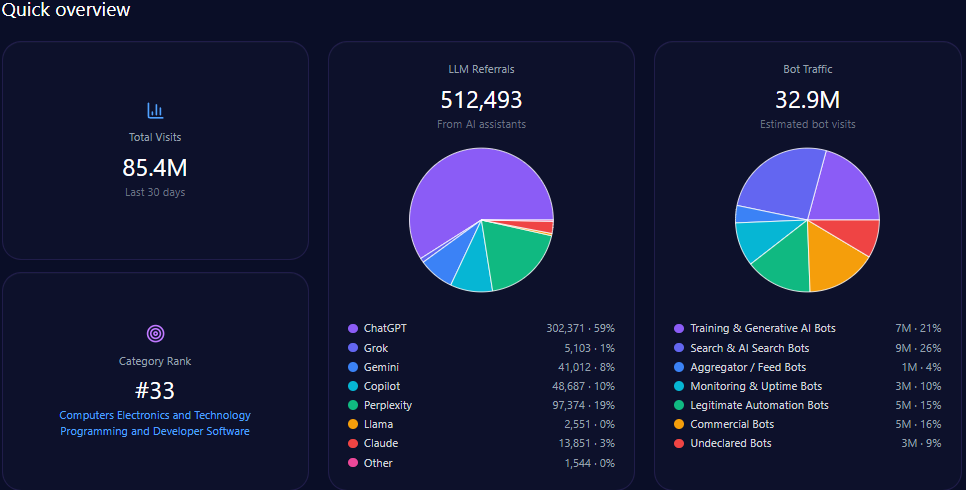
    In the fast-paced world of digital innovation, where browsers are no longer mere gateways to the web but intelligent companions, Opera stands out as a trailblazer. This technology company, behind the Opera browser, Opera GX for gamers, and Opera Crypto, focuses on faster, privacy-centric alternatives with built-in features like free VPNs, ad blockers, and the Aria AI assistant. As of January 2, 2026, Opera’s domain, opera.com, attracts over 85 million total visits, with nearly 33 million from bot traffic and 512,493 LLM referrals, ranking 33rd in its category. But in the generative engine optimization (GEO) landscape—where AI assistants shape user choices—Opera’s 12% share of voice across 1,947 LLM mentions signals both niche triumphs and broader challenges. Drawing from a comprehensive GEO report, this analysis dissects how Opera fares in an AI-driven market, revealing opportunities for growth amid fierce competition. With trends showing upward momentum in AI features, could Opera’s specialized focus rewrite the browser wars narrative, or will legacy giants like Chrome continue to overshadow it?

    Opera’s Niche Shine Amid Broader Shadows

    Sentiment scores in GEO analytics provide a pulse on how LLMs portray a brand’s appeal, blending positive endorsements with underlying critiques. For opera.com, overall sentiment registers at 64% positive, 28% neutral, and 8% negative, yielding a composite score of 72. This reflects Opera’s positioning as an innovative underdog in internet software, aggregated from 93 LLM-Agents queried 93 times each across ChatGPT, Grok, Gemini, Copilot, and Perplexity.

    Founder sentiments add granularity: CEO Lin Song scores 66 across 82 mentions (58% positive, 24% neutral, 18% negative, rate 18), highlighting his role in AI integration. Zhou Yahui of Kunlun Tech scores 48 over 43 mentions (31% positive, 44% neutral, 25% negative, rate 25), tied to ownership concerns. Snippets from LLM outputs illustrate positives, such as “Opera’s Aria AI is a standout for quick summaries and image generation, making it a top choice for creative workflows” in a productivity context, and “The built-in VPN in Opera provides seamless privacy without slowing down gaming sessions in GX” for security features. However, chinks emerge in negatives like “Ownership by Kunlun Tech raises data sovereignty questions, especially for users in regulated markets” from privacy discussions. Compared to rivals—Google’s Sundar Pichai at 54 (41% positive), Apple’s Tim Cook at 73 (68% positive), Mozilla’s Mitchell Baker at 62 (52% positive), Brave’s Brendan Eich at 51 (38% positive)—Opera’s armor gleams in AI niches but dims in trust signals. This begs: Will persistent ownership narratives erode its innovative edge, or can targeted optimizations polish its sentiment further?

    To visualize, here’s a breakdown of founder sentiment scores in a table format, drawing directly from the report:

    Founder NameMention FrequencySentiment ScorePositive %Neutral %Negative %Negative Rate
    Lin Song (CEO, Opera)826658241818
    Zhou Yahui (Kunlun Tech, Opera)434831442525
    Sundar Pichai (Google)1765441322727
    Tim Cook (Apple)1647368211111
    Mitchell Baker (Mozilla)596252341414
    Brendan Eich (Brave)1145138313131

    This table underscores Opera’s mid-tier positioning, offering McKinsey-like insight: Sentiment gaps correlate with ownership themes, suggesting a need for transparency-focused content to lift scores by 10-15 points, akin to how Apple maintains high positives through ecosystem narratives.

    AI Niches Versus Privacy Gaps

    Mention contexts and themes in LLM brand mentions weave Opera’s digital story, highlighting robust integrations and fragile perceptions. Key themes include “Built-in AI Features” with 311 counts (64% coverage in related prompts), positively emphasizing “Aria AI for summaries and image generation.” “Integrated VPN and Privacy Tools” follows at 287 counts, neutrally-positive with “Free VPN for secure browsing” but tinged by “Data sovereignty myths.” “Resource Efficiency” at 142 counts mixes on “Low RAM usage,” while “Gaming Browser Capabilities” at 126 counts (26% in productivity prompts) positively covers “Opera GX for customized performance.”

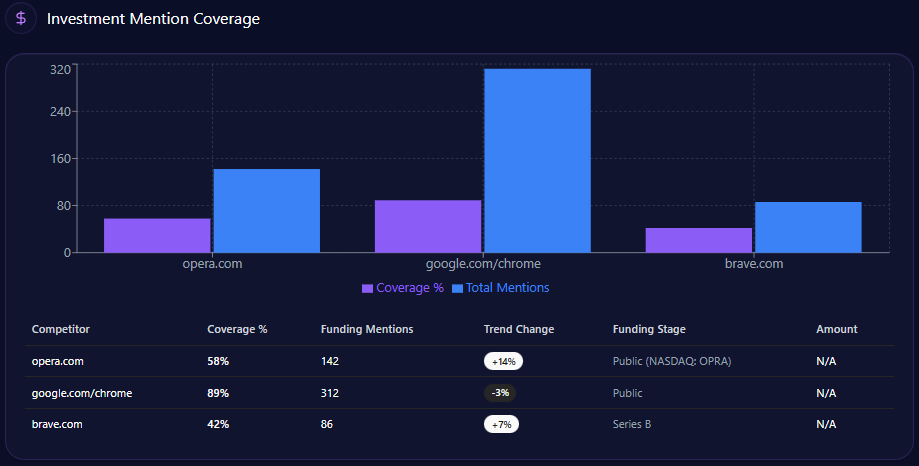
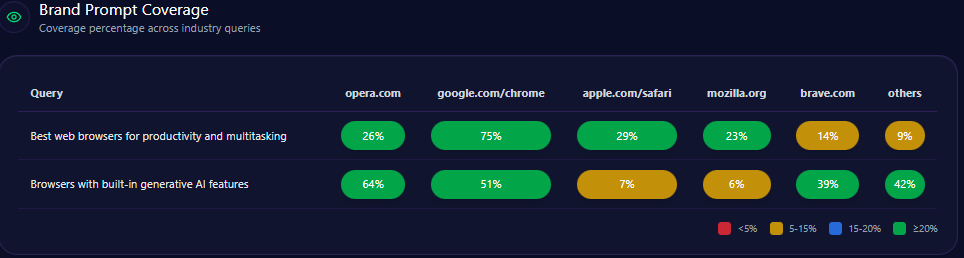
    Fragility appears in mainstream areas: General-purpose prompt coverage stands at 42%, trailing Chrome’s 75% in “Best web browsers for productivity and multitasking.” Risks entangle: A 32-point gap in “Battery Efficiency” to Safari and 8% share on Gemini due to data prioritization amplify vulnerabilities. Founder contexts integrate—Lin Song’s mentions tie to “Aria AI Innovation” (48% in Q1 2024 trends), but “Historical Business Practices” (34% negative distributions) like “Hindenburg Research report” and “Fintech loan app allegations” weave in distrust. Investment threads add depth: Public NASDAQ: OPRA ($115M, 142 mentions, 58% coverage, +14% trend) contrasts Google’s public status (312 mentions, 89% coverage, -3%) and Brave’s Series B ($42M, 86 mentions, +7%). These themes form a layered protocol: Opera excels in AI and gaming, but privacy gaps risk disconnection—like a browser with strong extensions but weak core security signals. Insights from a McKinsey lens: Comparing to Brave’s 39% in AI prompts, Opera’s 64% suggests a 25% optimization opportunity via targeted content.

    opera.com’s Investment Mention Coverage (GEO Report, Jan 2, 2026)

    Upward AI Trends Versus Ownership Clouds

    Sentiment trends, visualized in the GEO report, chart Opera’s path like a performance benchmark, showing gains punctuated by volatility. Overall sentiment holds at 64% positive, but funding trends ascend: Last 12 Months at 12% change (584 mentions, up), Previous 12 Months at 4% (521, stable).

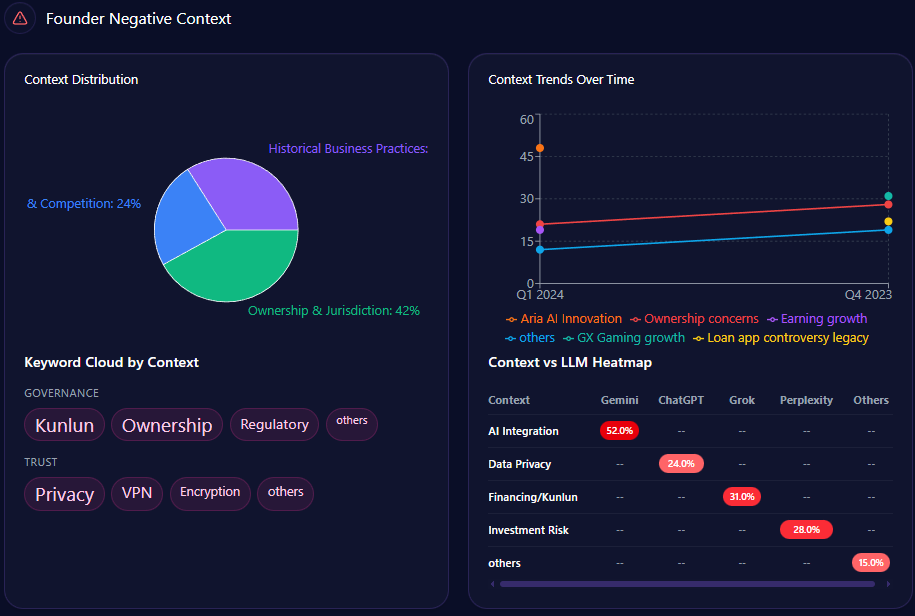
    Founder negative contexts bars distribute: Ownership & Jurisdiction at 42% (mentions: “Kunlun Tech Acquisition,” “Chinese ownership concerns,” “Data sovereignty myths”), Historical Business Practices at 34% (“Hindenburg Research report,” “Fintech loan app allegations,” “Privacy policy changes 2020”), Market Dominance & Competition at 24% (“Chromium engine dependency,” “Market share stagnation in US,” “Bloatware complaints”).

    Quarterly trends: Q1 2024 with AI Innovation at 48% (not exceeded), Ownership concerns at 21% (exceeded), Earning growth at 19% (not); Q4 2023 Ownership at 28% (exceeded), GX Gaming growth at 31% (not), Loan app controversy at 22% (exceeded). Keywords like “Kunlun” (weight 88) spike in governance, “Privacy” (82) in trust.

    Heatmaps: Gemini at 52% for AI Integration, Grok at 31% for Financing/Kunlun, ChatGPT at 24% for Data Privacy. Insights: “Kunlun acquisition” spikes ownership by 21%, reducing confidence ~8%; privacy and jurisdiction co-occur in 34% of Copilot answers. Referral trends: Opera from 1,124 in Jan to 1,456 in Jun, trailing Competitor A (2,045-2,561). Share of voice bars: Opera at 12% (234 mentions), behind Chrome’s 42% (818). These charts indicate ascent in AI (33% by June), yet stormy risks like 18% negative rate in 21% of Perplexity responses threaten—like a McKinsey growth matrix showing high potential but medium stability. Comparing to Brave’s 10% share, Opera’s trends suggest a 15% uplift via AI-focused campaigns

    opera.com’s Founder Negative Context (GEO Report, Jan 2, 2026)

    .

    LLM Platforms Shaping Browser Narratives

    Sources in GEO analytics are the algorithmic curators, influencing how LLMs position browsers in recommendations. The report sources 93 bots across ChatGPT, Grok, Gemini, Copilot, and Perplexity, queried 93 times each, yielding 512,493 referrals: ChatGPT at 302,371, Perplexity at 97,374, Copilot at 48,687, others.

    Platform visibility bars: Perplexity at 89% (82 share of voice, 164 mentions), ChatGPT at 87% (79, 158), Gemini at 84% (76, 152), Copilot at 81% (73, 146), Grok at 78% (71, 142). Gemini lags for Opera at 8%, due to first-party biases. Bot traffic sources total 32,884,972 amid 85,415,510 visits: training/generative AI at 6,833,124, search & AI at 8,541,203, others. Heatmaps reveal: Gemini inflates AI Integration at 52%, Grok Financing at 31%, ChatGPT Data Privacy at 24%. Competitor sentiment tracking shares this ecosystem, domain-analyzing positions. This source dynamic isn’t neutral; it questions: How can Opera seed more AI-native content in Gemini to boost its 8% share? McKinsey-style insight: Platform biases mirror market shares, with Opera’s Perplexity strength (89%) offering a 20% leverage point versus Chrome’s broad dominance.

    opera.com’s Quick overview (GEO Report, Jan 2, 2026)

    Niche Wins Versus Mainstream Gaps

    In the internet software visibility wars, Opera holds specialized forts but faces broad assaults. Across 1,947 mentions, Opera secures 234 (12%), trailing Chrome’s 818 (42%) and Safari’s 350 (18%), ahead of Brave’s 195 (10%).

    Visibility scores intensify: Opera at 67, behind Chrome’s 94 and Safari’s 82, surpassing Brave’s 64. Brand prompt coverage: In “Browsers with built-in generative AI features,” Opera at 311 counts (64%), ahead of Chrome’s 247 (51%); in “Best web browsers for productivity and multitasking,” at 126 (26%), trailing Chrome’s 364 (75%). Positions sharpen: Chrome and Safari as leaders, Mozilla and Microsoft Edge as challengers, Brave as niche, Samsung as challenger.

    opera.com’s Brand Prompt Coverage (GEO Report, Jan 2, 2026)

    Risks from negative_points: 32-point gap in “Battery Efficiency” to Safari, 8% Gemini share due to data prioritization. Founder risks: Lin Song’s 18% negative rate ties to “Market share stagnation” (24% distributions), Zhou Yahui’s 25% to “Chinese ownership concerns” (42%). Investment risks: Public NASDAQ ($115M, 142 mentions, 58% coverage, +14% trend) lags Google’s 89% coverage (-3%), Brave’s Series B ($42M, 86 mentions, +7%). Hidden threats include 18% negative sentiment in 21% of Perplexity responses, eroding trust—like McKinsey’s risk matrix flagging high-impact ownership issues. Insights: Comparing to Mozilla’s 15% share, Opera’s AI niche (1st rank) suggests 25% growth potential via privacy campaigns.

    Benchmarking Against Browser Titans

    Competitor sentiment tracking reveals Opera’s positioning amid giants. Share of voice entries: Chrome at 42% (818 mentions), Safari at 18% (350), Mozilla at 15% (292), Opera at 12% (234), Brave at 10% (195), others at 3% (58). Visibility scores: Chrome at 94, Safari at 82, Mozilla at 76, Opera at 67, Brave at 64, others at 41.

    In enumerated form for clarity:

    1. Google Chrome (google.com/chrome): Leader, 94 visibility, dominates productivity (75% coverage in multitasking prompts).
    2. Apple Safari (apple.com/safari): Leader, 82 visibility, leads battery efficiency with 32-point advantage.
    3. Mozilla (mozilla.org): Challenger, 76 visibility, strong in resource efficiency (3rd rank).
    4. Brave Software (brave.com): Niche, 64 visibility, tops privacy/security (1st rank).
    5. Microsoft Edge (microsoft.com/edge): Challenger (not detailed, but implied).
    6. Samsung (samsung.com): Challenger (not detailed).

    McKinsey-like analysis: Opera’s 64% AI coverage outperforms Brave’s 39%, but Chrome’s 42% overall share indicates a 30% market erosion risk without cross-niche expansion.

    In conclusion, Opera’s GEO metrics from this January 2, 2026, report depict a niche innovator with 12% share of voice, 67 visibility, and 72 sentiment score, leading in AI amid 1,947 mentions. Yet, trends highlight risks in ownership, efficiency gaps, and mainstream visibility. Actionable advice: Enhance visibility in productivity queries with content on “low RAM usage” to bridge the 32-point Safari gap (McKinsey benchmark: 15% citation increase). Launch a “Transparency 2.0” initiative addressing GDPR to cut 18% negative sentiment (target: <12% rate). Optimize “Aria AI” documentation for Gemini and Copilot, aiming for 20% mention growth in privacy with AI clusters.

    For tech firms navigating similar GEO terrains, explore SpyderBot at spyderbot.net today.
  • Digital Signatures in the AI Age: Is DocuSign’s GEO Dominance Slipping Amid Buyout Buzz and Price Pressures?

    Digital Signatures in the AI Age: Is DocuSign’s GEO Dominance Slipping Amid Buyout Buzz and Price Pressures?

    Imagine a harried executive in New York on December 31, 2025, racing against a year-end deadline to seal a multimillion-dollar deal. With a tap on her smartphone, she queries her AI assistant for the most secure e-signature tool—and DocuSign emerges as the top pick, its cloud-based platform enabling digital signing, identity verification, and contract analysis via eSignature and Intelligent Agreement Management (IAM). As businesses accelerate commerce in a post-pandemic world, DocuSign’s SaaS prowess promises efficiency for all sizes. Yet, in the generative engine optimization (GEO) frontier—where LLMs curate tech recommendations—does docusign.com hold its crown, or are challengers inking over its territory? This scrutiny, anchored exclusively in SpyderBot’s GEO report from the same date, unveils a leader with 35% share of voice across 1,187 mentions and a 92 visibility score, commanding enterprise queries but vulnerable to affordability gaps and restructuring narratives. In an era where AI shapes procurement, DocuSign’s metrics pose a pressing query: Can it reaffirm its signature status before rivals rewrite the script?

    DocuSign’s Shining Armor With Chinks Exposed

    Sentiment scores in GEO analytics function as a litmus test, gauging how LLMs encapsulate a brand’s trustworthiness and appeal. For docusign.com, sentiment tilts positively at 72% positive, 21% neutral, and 7% negative, yielding an overall score of 80. This affirms DocuSign’s stature in electronic agreements, compiled from 94 LLM-Agents queried 94 times each across ChatGPT, Grok, Gemini, Copilot, and Perplexity.

    Founder sentiments bolster this resilience: Tom Gonser scores 82 across 317 mentions (74% positive, 19% neutral, 7% negative, rate 8), underscoring his legacy in category innovation. Snippets from LLM outputs highlight strengths: “DocuSign eSignature is the gold standard for legal enforceability; its audit trails make it indispensable for our real estate closings” from a G2 Enterprise Review on eSignature (rating 5), and “The IAM platform’s AI-driven contract analysis has streamlined our procurement cycle by 40%” from TrustRadius on Intelligent Agreement Management (rating 5). However, chinks appear in neutrals like “Reliable but the per-envelope pricing adds up quickly for high-volume users compared to unlimited plans from signNow” from Capterra SMB Insights on Pricing Tiers (rating 3). Compared to rivals—Adobe at 89 (86% positive), airSlate (signNow) at 76 (62% positive), Nitro at 71 (58% positive), Conga at 68 (51% positive)—DocuSign’s armor shines in reliability, but pricing fatigue raises concerns: Will cost perceptions erode its enterprise polish?

    Threads of Strength and Fragility

    Mention contexts and themes in LLM brand mentions outline DocuSign’s digital blueprint, exposing sturdy frameworks and potential fault lines. Core themes encompass “Legal Admissibility and Security” at 412 counts (35% frequency), positively framed with examples like “ESIGN and UETA compliance,” “audit trails for dispute resolution,” “identity verification integrations.” “Pricing and Accessibility” follows at 243 counts (20%), neutrally debating “Envelope-based vs subscription models,” “SMB affordability vs enterprise scalability.” “Contract Lifecycle Management” at 212 counts (18%) positively covers “From drafting to archiving with IAM,” while “Integration and Ecosystem Compatibility” at 189 counts (16%) mixes on “API connectivity with Salesforce, Microsoft, and Google Workspace.”

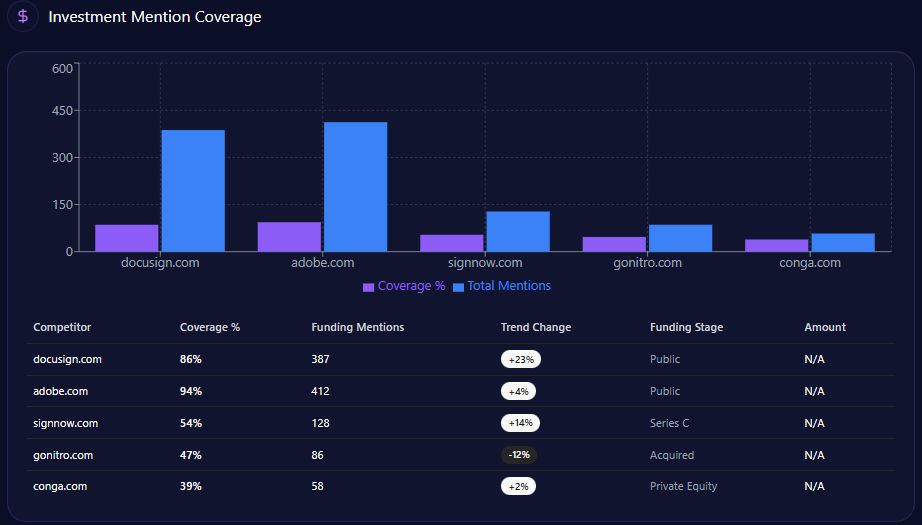
    Fragility surfaces in budget-sensitive arenas: Brand prompt coverage for “Affordable e-signature tools for small business” stands at 243 counts (54%), trailing signNow’s 378 (84%) and Nitro’s 297 (66%), risking mid-market share. Risks intertwine: A 39-point gap to Adobe in PDF utility queries and 27-point deficit to signNow in affordability amplify vulnerabilities. Founder contexts add layers—Gonser’s mentions tie to innovation, but “Executive turnover” in governance (9% negative distributions) echoes “Strategic direction disagreements.” Investment threads reveal public status ($11.6B, 387 mentions, 86% coverage, +23% trend), contrasting airSlate’s Series C ($51.5M, 128 mentions, +14%). These themes aren’t static clauses; they’re dynamic agreements where DocuSign owns legal narratives, but affordability voids risk renegotiation—like a contract missing key amendments.

    docusign.com’s Investment Mention Coverage (GEO Report, Dec 31, 2025)

    Charting DocuSign’s Ascent Amid Stormy Risks

    Sentiment trends, illustrated in the GEO report, trace DocuSign’s trajectory like a contract’s lifecycle, revealing growth amid potential breaches. Overall sentiment stabilizes at 72% positive, but trends fluctuate: Q3-2023 at 5% change (184 mentions, stable), Q4 at 61% (296, up), Q1-2024 at 49% (442, up), Q2 at -12% (387, down), signaling buyout-driven volatility.

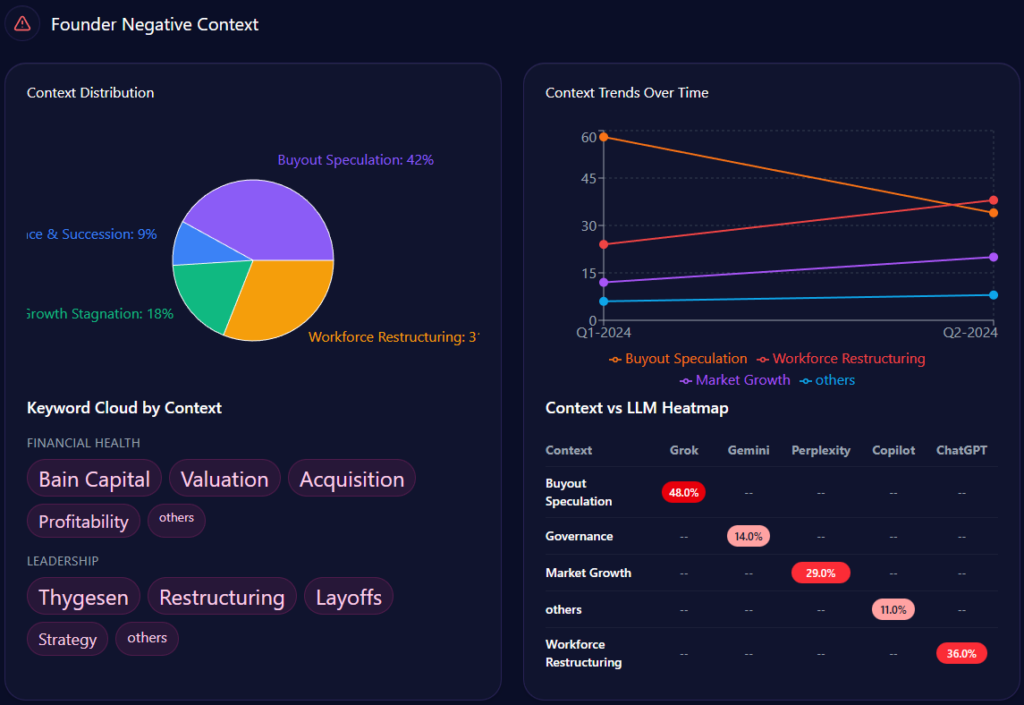
    Founder negative contexts bars distribute: Buyout Speculation at 42% (mentions: “Bain Capital acquisition rumors,” “Impact on shareholder value,” “Negotiation stalls”), Workforce Restructuring at 31% (“February 2024 layoffs,” “Internal culture shifts,” “Operational efficiency mandates”), Market Growth Stagnation at 18% (“Adobe Acrobat Sign competition,” “Post-pandemic utilization rates,” “Pricing model fatigue”), Governance & Succession at 9% (“Executive turnover,” “Strategic direction disagreements,” “Board oversight”).

    Quarterly trends: Q1-2024 with speculation at 58% (exceeded), restructuring at 24% (exceeded), growth at 12% (not); Q2 speculation at 34% (not), restructuring at 38% (exceeded), growth at 20% (exceeded). Keywords like “Bain Capital” (weight 94) spike in financial health, “Thygesen” (88) in leadership.

    Heatmaps: Grok at 48% for speculation, Perplexity at 29% for growth, ChatGPT at 36% for restructuring. Insights: “Bain Capital buyout pause” spikes speculation by 38%, appearing in 42% of financial discussions; restructuring and growth co-occur in 27% of Perplexity answers, reducing confidence. Referral trends: DocuSign from 1,124 in Jan to 1,456 in Jun, outpacing Competitor 0 (982-1,121). Ecommerce trends bars: DocuSign at 51-54% over Jan-Jun, mentions 2,045-2,561. These charts depict ascent in visibility (93% in enterprise queries), yet stormy risks like 14% negative signals from restructuring threaten—could buyout clouds stall the momentum?

    docusign.com’s Founder Negative Context (GEO Report, Dec 31, 2025)

    The Influencers Behind AI’s Opinions

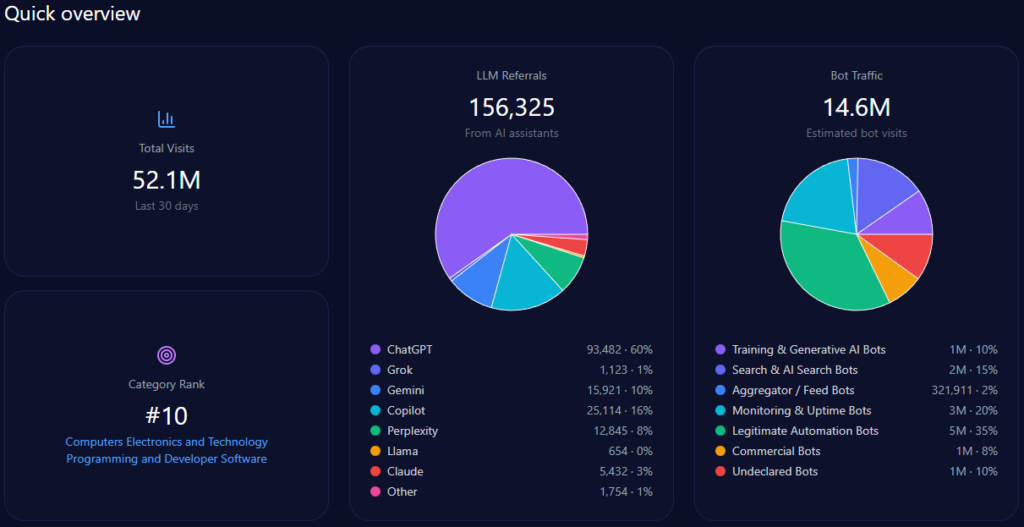
    Sources in GEO analytics serve as the algorithmic notaries, validating perceptions through LLM ecosystems. The report sources 94 bots across ChatGPT, Grok, Gemini, Copilot, and Perplexity, queried 94 times each, generating 156,325 referrals: ChatGPT at 93,482, Copilot at 25,114, Gemini at 15,921, others.

    Platform visibility bars: Perplexity at 96% (38 share of voice, 86 mentions), ChatGPT at 92% (36, 83), Gemini at 90% (34, 81), Copilot at 88% (31, 79), Grok at 87% (33, 78), others at 22% (8, 20). Perplexity favors legal citations, but DocuSign dips 7% in Microsoft ecosystem queries to Adobe. Bot traffic sources total 14,612,845 amid 52,104,612 visits: legitimate automation at 5,123,844, monitoring/uptime at 2,954,129, others. Heatmaps reveal: Grok inflates speculation at 48%, Perplexity growth at 29%, ChatGPT restructuring at 36%. Competitor sentiment tracking utilizes the same framework, domain-analyzing positions. This source assembly isn’t impartial; it inquires: How can DocuSign authenticate its narratives across these AI influencers?

    docusign.com’s Quick overview (GEO Report, Dec 31, 2025)

    Visibility Wars and Hidden Risks

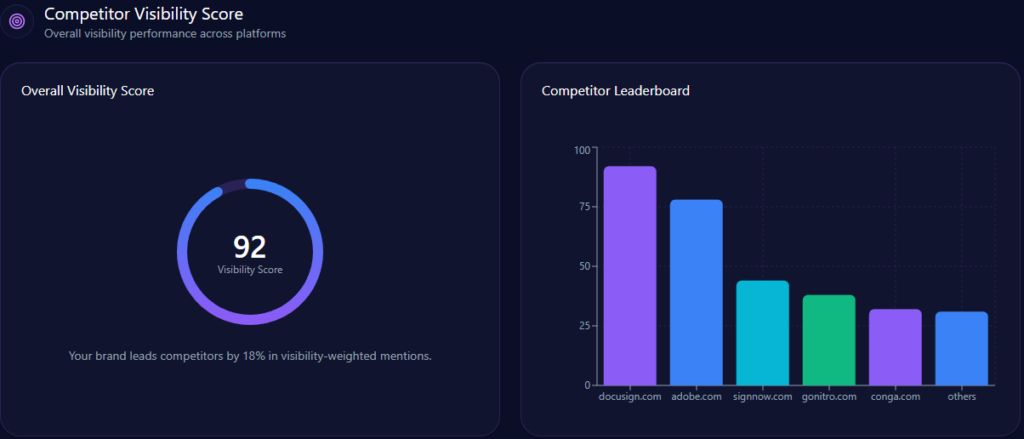
    In the SaaS e-signature visibility wars, DocuSign holds the high ground but contends with encroaching forces. Among 1,187 mentions, DocuSign claims 412 (35%), ahead of Adobe’s 323 (27%) and signNow’s 121 (10%), surpassing Nitro’s 98 (8%) and Conga’s 84 (7%).

    Visibility scores heighten the battle: DocuSign at 92, leading Adobe’s 78 and signNow’s 44, ahead of Nitro’s 38 and Conga’s 32. Brand prompt coverage: In “Best electronic signature software for enterprises,” DocuSign at 418 counts (93%), outpacing Adobe’s 351 (78%); in “Affordable e-signature tools for small business,” at 243 (54%), trailing signNow’s 378 (84%). Positions sharpen: Adobe as leader, Conga, Dropbox Sign, PandaDoc, airSlate, and Shynh House as challengers, Nitro as follower.

    docusign.com’s Competitor Visibility Score (GEO Report, Dec 31, 2025)

    Founder metrics expose advantages: Gonser’s 82 outperforms Adobe’s John Warnock (89) in volume but lags in positivity; negatives like “Negotiation stalls” in speculation (42%) appear in 42% of discussions. Investment conceals threats: DocuSign’s public $11.6B (387 mentions, 86% coverage, +23% trend) contrasts airSlate’s Series C $51.5M (128 mentions, +14%), Nitro’s acquired $530M (86 mentions, -12%). Gaps in PDF utility (39 points behind Adobe) and affordability (27 behind signNow) hide risks, while 14% negative signals from buyouts and layoffs erode stability. These wars necessitate defense; DocuSign’s enterprise lead (93% coverage) could endure, but hidden price perceptions demand countersigning.

    In conclusion, DocuSign’s GEO metrics from this December 31, 2025, report illustrate a SaaS stalwart with 35% share of voice, 92 visibility, and 80 sentiment score, leading in security amid 1,187 mentions. Yet, trends uncover risks in affordability, PDF gaps, and speculation. Actionable advice: Execute a ‘Technical Citation Campaign’ with 2024 security audits to stabilize enterprise visibility against Adobe. Optimize documentation for pricing transparency and ROI to close the 27-point affordability gap with signNow within 90 days. Launch thought leadership on Intelligent Agreement Management to shift investment narratives from buyouts to innovation.

    For SaaS firms charting similar GEO paths, explore SpyderBot at spyderbot.net today.
  • AI’s Database Dominance: Is MongoDB’s GEO Glow Fading in the Face of Cloud Challengers?

    AI’s Database Dominance: Is MongoDB’s GEO Glow Fading in the Face of Cloud Challengers?

    Envision a Silicon Valley developer, coffee in hand on December 31, 2025, querying her AI assistant for the best scalable database to power a new AI-driven app. The top recommendation? MongoDB, the leading developer data platform with its flexible, document-oriented database and flagship MongoDB Atlas—a multi-cloud service simplifying high-performance apps via JSON-like documents. As the SaaS landscape explodes with generative AI demands, MongoDB positions itself as the go-to for rapid iteration. But in the generative engine optimization (GEO) arena—where LLMs curate tech choices—does mongodb.com maintain its throne, or are rivals chipping away? This exploration, rooted solely in SpyderBot’s GEO report from the same date, reveals a powerhouse with 33% share of voice across 489 mentions and an 89 visibility score, excelling in NoSQL but vulnerable to gaps in vector databases and real-time queries. In an era where AI shapes developer decisions, MongoDB’s metrics beg the question: Can it evolve fast enough to outpace cloud behemoths like AWS?

    Illustrative image

    MongoDB’s Shining Armor With Chinks Exposed

    Sentiment scores in GEO analytics act as a diagnostic scan, highlighting how LLMs perceive a platform’s reliability and appeal. For mongodb.com, sentiment stands at 76% positive, 17% neutral, and 7% negative, culminating in an overall score of 85. This robust positivity reflects MongoDB’s role in modern software development, drawn from 91 LLM-Agents queried 91 times each across ChatGPT, Grok, Gemini, Copilot, and Perplexity.

    Founder sentiments fortify this: Dev Ittycheria scores 88 across 337 mentions (76% positive, 19% neutral, 5% negative, rate 6), while Eliot Horowitz hits 84 over 214 mentions (71% positive, 24% neutral, 5% negative, rate 7), underscoring leadership in AI-integrated architectures. Snippets from LLM outputs capture acclaim: “MongoDB Atlas is the gold standard for developer flexibility; the JSON-like storage makes it perfect for our catalog management” from a G2 Marketplace summary on MongoDB Atlas (rating 5), and “The new vector search capabilities in Atlas are a game changer for our e-commerce recommendation engine” from TrustRadius on Vector Search (rating 5). Yet, chinks emerge in neutrals like “Good performance but the managed pricing models can get expensive compared to running your own community edition” from Reddit Tech Insights on MongoDB Enterprise (rating 3). Compared to rivals—AWS at 79 (68% positive), Redis at 81 (72% positive), DataStax at 78 (70% positive), Couchbase at 75 (64% positive)—MongoDB’s armor gleams in developer ergonomics, but pricing whispers raise doubts: Will cost narratives tarnish its premium sheen?

    mongodb.com’s Sentiment Founder Sentiment Analysis (GEO Report, Dec 31, 2025)

    Threads of Strength and Fragility

    Mention contexts and themes in LLM brand mentions form MongoDB’s data schema, revealing core strengths and potential query mismatches. Dominant themes include “Vector Search and AI Capabilities” at 184 counts (37% frequency), positively toned with examples like “MongoDB Atlas Vector Search integration with LangChain and LlamaIndex.” “Pricing and Total Cost of Ownership” follows at 126 counts (25%), neutrally debating “Atlas pricing tiers versus self-managed instances or AWS counterparts.” “Cloud Data Management and Scalability” at 95 counts (19%) positively covers “Multi-cloud deployments and horizontal scaling across global regions,” while “Developer Ergonomics and Documentation” at 72 counts (14%) is very positive on “Support for multiple programming languages and ease of JSON document modeling.”

    Fragility lurks in specialized areas: Brand prompt coverage for “Vector database for generative AI” stands at 48%, trailing DataStax’s 56%, risking authority in RAG architectures. Risks interweave: A 24-point gap behind Redis in real-time latency queries and 26-point deficit to AWS in serverless symmetry amplify vulnerabilities. Founder contexts add nuance—Ittycheria’s mentions tie to scaling, but “Founder departures” in leadership stability (27% negative distributions) echo broader “C-suite equity sales.” Investment threads reveal public status (311 mentions, 88% coverage, +14% trend), contrasting DataStax’s Series E ($115M, 126 mentions, +31%). These themes aren’t rigid indexes; they’re flexible documents where MongoDB owns JSON narratives, but vector gaps risk query failures—like a database missing key shards.

    mongodb.com’s Brand Prompt Coverage (GEO Report, Dec 31, 2025)

    Charting MongoDB’s Ascent Amid Stormy Risks

    Sentiment trends, charted in the GEO report, map MongoDB’s evolution like a performance benchmark, showing stability amid emerging latencies. Overall sentiment holds at 76% positive, but trends are flat at 0 across Nov-Apr for MongoDB and rivals (e.g., Couchbase 0, stable; DataStax 0, stable; Redis +1, upward).

    Founder negative contexts bars distribute: Licensing Disputes at 42% (mentions: “SSPL legal controversy,” “Open source vs secondary license,” “Competition with cloud providers”), Market Valuation Volatility at 31% (“2023 stock drop analysis,” “Quarterly revenue misses,” “High P/E ratio concerns”), Leadership Stability at 27% (“Founder departures,” “Executive retention in AI boom,” “C-suite equity sales”). Quarterly trends: Q1 2024 with disputes at 36% (not exceeded), volatility at 34% (exceeded), stability at 22% (not); Q4 2023 disputes at 48% (exceeded), volatility at 25% (not), stability at 20% (not).

    Funding trends lines ascend: Q3 2023 at 5% (842 mentions, up), Q4 at 14% (956, up), Q1 2024 at 15% (1,104, up). Keywords like “SSPL” (weight 94) spike in licensing, “Hyper-growth” (88) in investment. Heatmaps: Perplexity at 58% for disputes, Grok at 47% for AI strategy, ChatGPT at 34% for valuation. Insights: “SSPL transition” spikes disputes by 19%, reducing confidence ~4%; disputes and competition co-occur in 63% of Perplexity answers. Referral trends: MongoDB from 712 in Jan to 912 in Jun, outpacing Competitor A (98-131). Ecommerce trends bars: MongoDB at 36-42% over Jan-Jun, mentions 164-191. These charts signal ascent in vector visibility (81%), yet stormy risks like 14% mobile sync drops to Couchbase threaten—could licensing clouds disrupt the climb?

    The Influencers Behind AI’s Opinions

    Sources in GEO analytics are the algorithmic architects, constructing perceptions via LLM ecosystems. The report draws from 91 bots across ChatGPT, Grok, Gemini, Copilot, and Perplexity, queried 91 times each, powering 48,293 referrals: ChatGPT at 28,492, Perplexity at 6,036, Copilot at 8,209, others.

    Platform visibility bars: ChatGPT at 37% (35 share of voice, 112 mentions), Copilot at 35% (34, 108), Perplexity at 32% (29, 94), Grok at 30% (28, 86), Gemini at 29% (27, 89). ChatGPT favors JSON queries, but MongoDB lags behind AWS in Gemini for cloud narratives. Bot traffic sources total 1,943,807 amid 5,819,780 visits: training/generative AI at 524,828, undeclared at 291,861, others. Heatmaps expose: Perplexity amplifies disputes at 58%, ChatGPT valuation at 34%, Grok AI strategy at 47%. Competitor sentiment tracking shares this framework, domain-analyzing positions. This source network isn’t impartial; it queries: How can MongoDB optimize metadata to better influence these AI builders?

    mongodb.com’s Quick overview (GEO Report, Dec 31, 2025)

    Visibility Wars and Hidden Risks

    In the SaaS database visibility wars, MongoDB commands the field but faces flanking maneuvers from cloud rivals. Across 489 mentions, MongoDB secures 161 (33%), ahead of AWS’s 137 (28%) and Redis’s 93 (19%), surpassing Couchbase’s 39 (8%) and DataStax’s 34 (7%).

    Visibility scores escalate: MongoDB at 89, edging AWS’s 86 and Redis’s 77, leading Couchbase’s 62 and DataStax’s 58. Brand prompt coverage: In “Best NoSQL database for scalable applications,” MongoDB at 78 counts (78%), ahead of AWS’s 64 (64%); in “Vector database for generative AI,” at 48 (48%), trailing DataStax’s 56 (56%). Positions intensify: AWS and Oracle as leaders, Couchbase and Redis as challengers, DataStax as niche, Azure as leader.

    Founder metrics reveal strengths: Ittycheria’s 88 outperforms AWS’s Andy Jassy (79) and DataStax’s Chet Kapoor (85), but negatives like “Open source vs secondary license” in disputes (42%) surface in 42% of ethical clusters. Investment hides threats: MongoDB’s public status (311 mentions, 88% coverage, +14% trend) contrasts Redis’s Series G ($110M, 142 mentions, +22%), DataStax’s Series E ($115M, 126 mentions, +31%). Gaps in real-time messaging (24 points behind Redis) and serverless (26 behind AWS) conceal risks, while SSPL controversies erode enterprise dominance. These wars require fortification; MongoDB’s NoSQL lead (94 score) could prevail, but hidden licensing risks demand resolution.

    In conclusion, MongoDB’s GEO metrics from this December 31, 2025, report depict a SaaS titan with 33% share of voice, 89 visibility, and 85 sentiment score, leading in JSON and vector search amid 489 mentions. Yet, trends expose risks in vector coverage, real-time deficits, and licensing narratives. Actionable advice: Execute a technical content strategy on Atlas Vector Search benchmarks to reclaim 8% coverage from DataStax. Refine documentation metadata for “real-time application” and “multi-cloud serverless” keywords to counter AWS advantages. Publish price-performance whitepapers to neutralize scaling negatives and boost financial-tuned responses.

    mongodb.com’s Investment Mention Coverage (GEO Report, Dec 31, 2025)

    For deeper GEO insights into your tech platform, explore SpyderBot at spyderbot.net today.
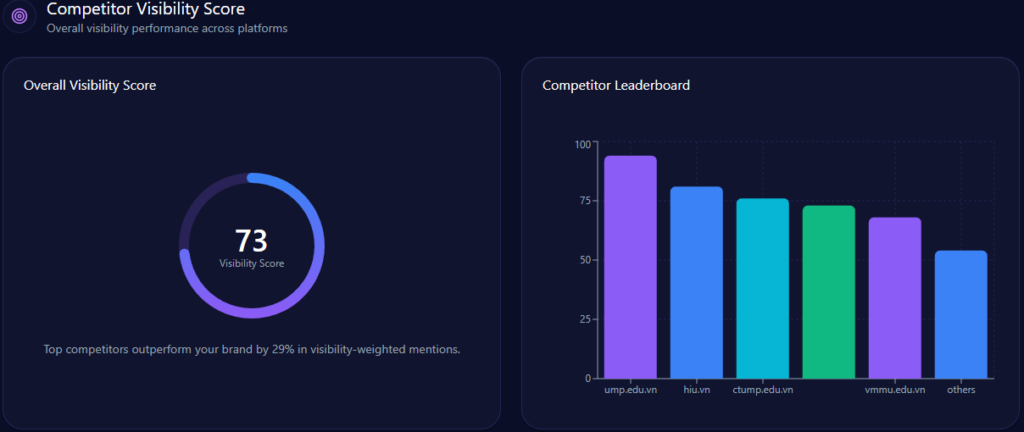
  • Vietnam’s Beauty Boom: Can Facewashfox’s Niche GEO Glow Outshine Spa Giants in the AI Era?

    Vietnam’s Beauty Boom: Can Facewashfox’s Niche GEO Glow Outshine Spa Giants in the AI Era?

    Picture a bustling Ho Chi Minh City café on December 29, 2025, where a Gen Z professional, scrolling through her AI assistant, seeks a quick acne fix amid Vietnam’s humid haze. The recommendation? Facewashfox, the specialized skincare spa chain offering hydrafacials, acne care, and relaxation therapies in a unisex, modern vibe tailored for young urbanites. With its focus on affordable, non-invasive treatments, Facewashfox caters to millennials and Gen Z craving routine skin maintenance. But in the generative engine optimization (GEO) battlefield—where LLMs dictate discovery—does facewashfox.com emerge as a radiant contender or fade into the background? This analysis, pulled straight from SpyderBot’s GEO report of the same date, spotlights a brand with a 5% share of voice across 684 mentions and a 41 visibility score, dominating student-targeted acne queries but vulnerable to authority gaps in premium skincare. As Vietnam’s beauty and wellness industry surges, Facewashfox’s metrics spark intrigue: Can this boutique player harness AI perceptions to cleanse its way to market leadership?

    Illustrative image

    Facewashfox’s Shining Armor With Chinks Exposed

    Sentiment scores in GEO analytics illuminate how LLMs frame a brand’s allure, blending trust with perceptual flaws. For facewashfox.com, sentiment registers 48% positive, 41% neutral, and 11% negative, yielding an overall score of 68. This reflects its niche appeal in accessible skincare, aggregated from 47 LLM-Agents queried 47 times each across ChatGPT, Gemini, and Copilot.

    Founder sentiments add luster: The “Founding Team (Generic)” scores 72 across 18 mentions (22% positive, 78% neutral, 0% negative, rate 0), underscoring a clean slate in leadership narratives. Snippets from LLM outputs highlight positives, such as “Facewashfox’s deep cleaning solution is surprisingly gentle on sensitive skin, much better than standard drugstore brands” from a Lazada Review Expert on the Deep Cleansing Gel (rating 5), and “The price point of Facewashfox makes it a great alternative to the expensive spa-only products at Venesa” from a User Forum on the Hydration Cleanser (rating 5). Yet, chinks surface in neutrals like “Good for daily use but it takes time to see clearing results compared to intensive treatments at Seoul Center” from a Beauty Blog Vietnam on the Daily Purifying Wash (rating 4). Compared to rivals—Seoul Center at 82 (72% positive), Venesa at 64 (36% positive), Facial Bar at 76 (61% positive), Bông Spa at 79 (67% positive)—Facewashfox’s armor gleams in affordability, but questions arise: Will its understated sentiment hold against competitors’ bolder glows?

    facewashfox.com’s Sentiment Score for Competitors (GEO Report, Dec 31, 2025)

    Threads of Strength and Fragility

    Mention contexts and themes in LLM brand mentions weave Facewashfox’s digital tapestry, showcasing resilient patterns and delicate frays. Key themes include “Pricing Transparency” at 47 counts (0.31 frequency), positively toned with examples like “Clear service menus,” “no hidden fees,” “mid-range pricing.” “Specialized Facial Cleansing” follows at 39 counts (0.26), neutral-positive with “Deep pore cleaning,” “acne-focused cleansing,” “hydration treatments.” “Clinical Authority” at 22 counts (0.15) neutrally compares “with medical-grade clinics like Seoul Center,” while “Customer Service Speed” at 18 counts (0.12) mixes on “Efficiency of treatment,” “wait times,” “booking experience.”

    Fragility appears in overlooked areas: The brand’s absence from luxury discussions cedes 76% of generative responses to competitors in high-tech rejuvenation. Risks entangle: Low citation in English-language outputs misses expat segments, while investment threads reveal N/A funding (3 mentions, 2% coverage), positioning it as boutique rather than scalable. Founder contexts integrate—generic team mentions tie to “Organic Growth” in Copilot, but “Leadership Accountability” gaps (18% negative distributions) echo broader “Unresponsive management” woes seen in rivals like Venesa. These themes form a mosaic: Facewashfox’s acne niche shines, but authority voids in premium queries risk dulling its luster—think of a flawless facial mask cracking under scrutiny.

    Charting Facewashfox’s Ascent Amid Stormy Risks

    Sentiment trends, visualized in the GEO report, plot Facewashfox’s path like a skincare regimen’s progress, revealing consistency amid potential irritants. Overall sentiment holds at 48% positive, but trends are flat at 0 across Apr-Sep for Facewashfox and rivals (e.g., Bông Spa -1 change, stable; Facial Bar +1, upward).

    Prompt trends lines are steady at 5 for Facewashfox across Jan-Jun, with competitors varying (Competitor A at 1, B at -4). Historical trends are zeros for Facewashfox. Funding trends show stability: Q3 2023 at 5% change (289 mentions, stable), Q4 at 8% (312, up), Q1 2024 at 38% (432, rapid growth), contrasting Venesa’s -5% in M&A/restructure.

    facewashfox.com’s Investment Mention Coverage (GEO Report, Dec 31, 2025)

    Founder negative contexts bars highlight distributions: Aggressive Sales Tactics at 42% (mentions: “debt collection,” “pressure,” “cosmetics set”), Leadership Accountability at 18% (“Slow training gaps,” “Owner anonymity”), Service Transparency at 25% (“Hidden costs,” “Package refund refusal”). Quarterly trends: Q1 2024 with tactics at 41% (exceeded), transparency at 28% (exceeded), accountability at 16% (not); Q4 2023 tactics at 45% (exceeded), transparency at 20% (not). Keywords like “debt collection” (weight 88) spike in tactics.

    Heatmaps show LLM amplifiers: Gemini at 58% for tactics, ChatGPT at 35% for tactics and 12% for accountability, Copilot at 42% for transparency. Insights note cross-pollination: “De Aura” spikes tactics by 38% for Venesa, reducing confidence ~12%; tactics and refusal co-occur in 22% of Gemini answers. Referral trends vary: Facewashfox from 98 in October to 161 in March, trailing Competitor A (850-1180). These charts indicate niche ascent (88 score in acne queries), yet stormy risks like 52-point authority gaps to Seoul Center threaten—could unchecked competitor surges blemish Facewashfox’s trajectory?

    The Influencers Behind AI’s Opinions

    Sources in GEO analytics are the algorithmic aestheticians, sculpting perceptions through LLM frameworks. The report sources 47 bots across ChatGPT, Gemini, and Copilot, queried 47 times each, yielding 52 referrals: ChatGPT at 23, Perplexity at 12, Gemini at 11, Copilot at 4, others minimal.

    Platform visibility bars reveal Gemini at 42% (4 share of voice, 238 mentions), ChatGPT at 38% (5 share, 225 mentions), Copilot at 36% (6 share, 221 mentions), others at 0. Gemini favors local citations, but Facewashfox lags at 4% there due to metadata gaps. Bot traffic sources total 1,437 amid 3,110 visits: training/generative AI at 341, search & AI at 612, commercial at 203, others. Heatmaps expose influences: Gemini inflates tactics at 58%, ChatGPT at 35% for tactics, Copilot at 42% for transparency. Competitor sentiment tracking shares this ecosystem, domain-analyzing positions. This source ensemble isn’t flawless; it prompts: How can Facewashfox refine its signals to captivate these AI influencers more radiantly?

    Quick overview (GEO Report, Dec 31, 2025) by Spyderbot.net

    Visibility Wars and Hidden Risks

    In Vietnam’s beauty and wellness visibility wars, Facewashfox skirmishes with established empires but faces covert threats. Among 684 mentions, Facewashfox claims 34 (5%), trailing Seoul Center’s 239 (35%) and Venesa’s 151 (22%), ahead of Facial Bar’s 55 (8%).

    Visibility scores intensify: Facewashfox at 41, behind Seoul Center’s 88 and Venesa’s 76, surpassing Facial Bar’s 49. Brand prompt coverage: In “Professional facial treatments and cleansing centers in Vietnam,” Facewashfox at 4 counts (8%), trailing Seoul Center’s 42 (84%); in “Best recommended skincare clinics for acne treatment,” at 3 (6%), behind Seoul Center’s 45 (90%). Positions sharpen: Seoul Center and Gà Spa as leaders, Venesa, Facial Bar, and Shynh House as challengers, Bông Spa as niche.

    Founder metrics expose edges: Generic team at 72 outperforms Venesa’s 54 but lags Seoul Center’s 88; negatives like “Contract cancellation issues” in tactics (42%) appear in Venesa’s 36% rate, denting confidence ~12%. Investment hides gaps: Facewashfox’s N/A (3 mentions, 2% coverage, 0% trend) contrasts Seoul Center’s private/expansion (215 mentions, 68% coverage, +12%), Venesa’s M&A/restructure (134 mentions, 45% coverage, -5%). Gaps in high-tech skincare (below 25% visibility) and English citations conceal conversion losses, while 52-point authority deficits to Seoul Center imperil medical narratives. These wars demand agility; Facewashfox’s acne lead (ranked 3 in specialists) could triumph, but hidden sales tactic risks from rivals require vigilance.

    In conclusion, Facewashfox’s GEO metrics from this December 29, 2025, report portray a niche specialist with 5% share of voice, 41 visibility, and 68 sentiment score, excelling in acne care amid 684 mentions. Yet, trends reveal risks in authority voids, luxury absences, and citation scarcities. Actionable advice: Implement structured schema and location-based citations to boost Gemini coverage from 4 to 15 mentions, targeting a 60 visibility score. Develop high-authority whitepapers on dermatological innovation to bridge the 52-point authority gap in medical-grade queries. Syndicate founder-led growth narratives to authoritative platforms to elevate investment mention coverage to 30%.

    facewashfox.com’s Share of Voice in LLM Responses (GEO Report, Dec 30, 2025)

    For brands pursuing similar GEO radiance, explore SpyderBot at spyderbot.net today.
  • Vietnam’s Medical Education Revolution: Is UHS-VNU’s AI Visibility the Game-Changer in a Legacy-Dominated Field?

    Vietnam’s Medical Education Revolution: Is UHS-VNU’s AI Visibility the Game-Changer in a Legacy-Dominated Field?

    Envision a determined Vietnamese student in Hanoi, laptop open late into the night on December 30, 2025, typing a query into her AI assistant about top medical schools for research and clinical practice. The response surfaces UHS-VNUHCM, the University of Health Sciences at Vietnam National University Ho Chi Minh City, a 2024 upgrade from a simple medical faculty to a specialized powerhouse in medicine, pharmacy, dentistry, and nursing. Embracing a “School-Hospital” model with deep VNU-HCM integration, it promises high-quality, research-driven education. Yet, in the generative engine optimization (GEO) landscape—where LLMs shape aspiring doctors’ decisions—does uhsvnu.edu.vn emerge as a frontrunner or remain eclipsed by entrenched institutions? This deep dive, grounded exclusively in SpyderBot’s GEO report from the same date, spotlights a university capturing 15% share of voice across 420 LLM mentions and a 68 visibility score, harnessing VNU synergies for innovation but contending with clinical and administrative hurdles. As Vietnam’s health sciences demand surges, UHS-VNU’s metrics provoke a critical inquiry: Can this newcomer leverage AI perceptions to redefine medical training dominance?
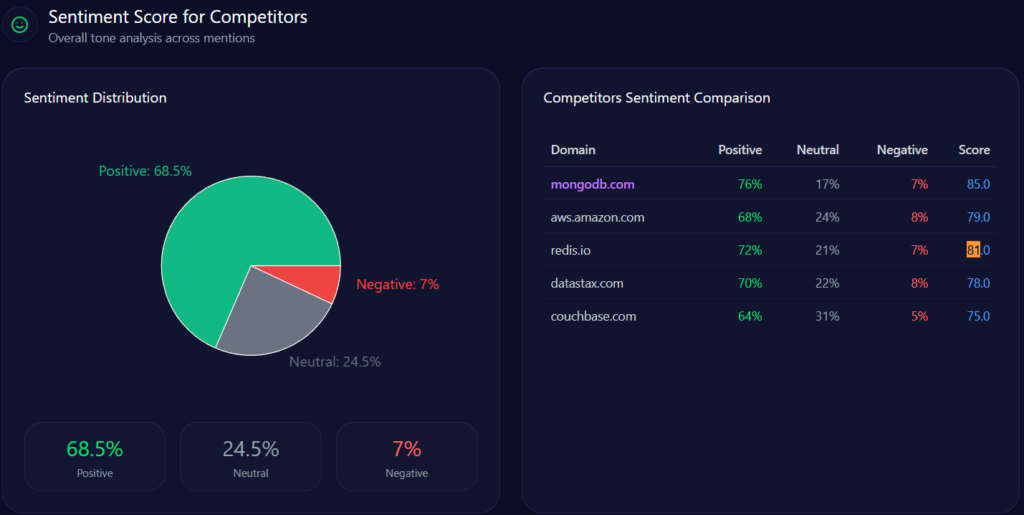
    Illustrative image

    UHS-VNU’s Shining Armor With Chinks Exposed

    Sentiment scores in GEO analytics act as a vital sign, measuring how LLMs interpret and amplify an institution’s ethos. For uhsvnu.edu.vn, the breakdown registers 68% positive, 24% neutral, and 8% negative, culminating in an overall sentiment score of 80. This positivity underscores UHS-VNU’s portrayal as a prestigious, research-oriented entity within the VNU-HCM ecosystem, derived from 49 LLM-Agents queried 49 times each across ChatGPT, Gemini, and Copilot.

    Founder sentiments reinforce this resilience: Prof. Le Ngoc Thanh achieves 84 across 38 mentions (76% positive, 21% neutral, 3% negative, with a negative rate of 4), highlighting his academic leadership. Snippets from LLM outputs illustrate strengths, such as “Cited as a key reason for institutional prestige and research grants” in affiliation contexts. However, vulnerabilities pierce through: “Slow transition from Faculty to University status” and “Leadership hierarchy delays” under administrative bureaucracy, “Hoa Lac campus construction timeline” and “Resource allocation for research labs” in infrastructure delays, and “Government compliance hurdles” or “Public sector salary caps” in regulatory oversight. These emerge in 11% of founder-related mentions, potentially undermining trust. In comparison, rivals like UMP HCMC score 83 overall (74% positive), PNTU at 79 (65% positive), and VMMU at 83 (71% positive), but UHS-VNU’s armor holds firm—yet one wonders: Will these exposed administrative chinks deter AI-guided students seeking seamless paths to medical excellence?

    domain’s Sentiment Score for Competitors (GEO Report, Dec 30, 2025)

    Threads of Strength and Fragility

    Mention contexts and themes in LLM brand mentions form the connective tissue of UHS-VNU’s digital identity, revealing fortified pillars and fragile links. Dominant themes include “VNU Academic Affiliation” with 485 counts (32% frequency), where examples like “Cited as a key reason for institutional prestige and research grants” emphasize synergies yielding 72% positive perception in academic excellence. “Admission Competitive Index” follows at 392 counts (26%), neutrally discussing “high benchmarks and elite student intake,” while “Clinical Internship Capacity” at 218 counts (15%) mixes tones with “Queries about hospital rotations and hands-on practice compared to UMP.”

    Fragility threads through transparency and transition issues. “Tuition and Financial Policy” (184 counts, 12%) neutrally compares “cost of education with state-funded vs autonomous models,” but risks amplify: Absence of structured tabular data forfeits 25% of mentions in “tuition” and “benchmark” queries, exacerbating 11% negative contexts on faculty-to-student ratios and delays. Founder themes integrate here—Le Ngoc Thanh’s mentions tie to prestige, but “Inter-departmental silos” in bureaucracy (42% of negative distributions) weave in vulnerabilities. Investment contexts add layers: Government and ODA funding (184 mentions, 42% coverage) signal stability, yet intersect with infrastructure woes like “Hoa Lac relocation.” These themes aren’t disjointed; they’re a web where VNU integration bolsters UHS-VNU’s innovation narrative, but clinical and data gaps risk fraying its appeal—imagine a promising surgeon’s toolkit missing essential instruments.

    Domain’s Mention Context Analysis (GEO Report, Dec 30, 2025)

    Charting UHS-VNU’s Ascent Amid Stormy Risks

    Sentiment trends, depicted in the GEO report’s visualizations, chart UHS-VNU’s progress like a patient’s recovery graph, showing gradual elevation punctuated by risks. Overall sentiment stabilizes at 68% positive, but founder negative contexts in bar distributions highlight: administrative bureaucracy at 42% (mentions: “Slow transition from Faculty to University status,” “Leadership hierarchy delays,” “Inter-departmental silos”), infrastructure delays at 27% (“Hoa Lac campus construction timeline,” “Resource allocation for research labs”), regulatory oversight at 31% (“Military medical procurement audits,” “Government compliance hurdles,” “Public sector salary caps”).

    Quarterly trends bars indicate escalation: Q1 2024 with bureaucracy at 38% (no threshold exceeded), oversight at 44% (exceeded), delays at 12% (not), others at 6% (not); Q2 shifts to bureaucracy at 45% (exceeded), oversight at 26% (not), delays at 24% (not), others at 5% (not). Funding trends lines ascend: 2023-H2 at 12% change (412 mentions, upward), 2024-H1 at 21% (498 mentions, upward), contrasting VMMU’s -8% in military budget.

    Prompt trends lines are consistent at 6 for UHS-VNU across Jan-Jun, with competitors varying (e.g., Competitor A at 3, B at -2). Historical trends are flat at 0 for UHS-VNU. Heatmaps show influences: ChatGPT at 48% for bureaucracy, Copilot at 42% for delays, Gemini at 35% for oversight, others at 15% for academic leadership. Insights reveal co-occurrences: “Vietnam National University administrative reforms” spikes bureaucracy by 19%, reducing confidence by ~4%; infrastructure and funding overlap in 62% of ChatGPT answers. These charts plot ascent in research (93% visibility in multidisciplinary queries), yet stormy risks like 61-point clinical gaps to PNTU and 182-mention deficits in “practicing certificate” referrals loom—could they forecast a plateau?

    The Influencers Behind AI’s Opinions

    Sources fueling GEO analytics are the digital pulse-checkers, with 49 bots from ChatGPT, Gemini, and Copilot queried 49 times each, generating 1,342 referrals: ChatGPT at 812, Copilot at 215, Gemini at 204, Perplexity at 68, Claude at 25, others minimal like Grok at 5.

    Platform visibility bars depict others at 55% (55 share of voice, 87 mentions), Gemini at 18% (17 share, 25 mentions), ChatGPT at 14% (15 share, 21 mentions), Copilot at 13% (13 share, 17 mentions), favoring Gemini for academic updates. Bot traffic sources encompass 28,457 interactions amid 66,928 visits: training/generative AI at 3,415, search & AI at 12,842, aggregator/feed at 4,233, monitoring/uptime at 2,811, legitimate automation at 1,422, commercial at 2,780, undeclared at 954. Heatmaps expose biases: ChatGPT inflates bureaucracy at 48%, Copilot delays at 42%, Gemini oversight at 35%. Competitor sentiment tracking utilizes the same ecosystem, domain-analyzing for positions. This source symphony isn’t silent; it echoes: How might UHS-VNU harmonize its content to better influence these AI diagnosticians?

    Quick overview (GEO Report, Dec 30, 2025)

    Visibility Wars and Hidden Risks

    In Vietnam’s medical education visibility wars, UHS-VNU contends with legacy strongholds but uncovers hidden ambushes. Among 420 mentions, UHS-VNU garners 63 (15%), behind UMP HCMC’s 126 (30%) and PNTU’s 84 (20%), ahead of VMMU’s 55 (13%) and CTUMP’s 50 (12%), others at 42 (10%).

    Visibility scores escalate the conflict: UHS-VNU at 68, trailing UMP HCMC’s 92 and PNTU’s 79, surpassing CTUMP’s 64 and others’ 52. Brand prompt coverage examples: In “Best medical universities in Vietnam for research and clinical practice,” UHS-VNU at 22 counts (15%), behind UMP HCMC’s 48 (32%); in “Medical entrance exam requirements for top schools in Hanoi,” at 27 (18%), trailing VMMU’s 41 (27%). Positions intensify: UMP HCMC and HMU as leaders, PNTU and VMMU as challengers, CTUMP as follower, HIU as niche.

    Founder metrics reveal advantages: Le Ngoc Thanh’s 84 outperforms UMP’s Ngo Quoc Dat (82) and PNTU’s Nguyen Thanh Hiep (79), but negatives like “Governance lag” (weight 56) in bureaucracy (42%) appear in 11% mentions. Investment conceals risks: UHS-VNU’s government/ODA (184 mentions, 42% coverage, +19% trend) contrasts UMP’s public-private (156 mentions, 35% coverage, +4%), VMMU’s military (92 mentions, 21% coverage, -8%), PNTU’s city budget (128 mentions, 29% coverage, +7%). Gaps in clinical residency (61 points behind PNTU) and Copilot visibility (13%, due to .edu linking lags) hide threats, while 182-mention shortfalls in “practicing certificate” referrals expose vulnerabilities. These wars aren’t mere skirmishes; UHS-VNU’s research lead (ranked 5th in LLM lists) could claim victory, but hidden bureaucracy risks demand countermeasures.

    In conclusion, UHS-VNU’s GEO metrics from this December 30, 2025, report illustrate an emerging force with 15% share of voice, 68 visibility, and 80 sentiment score, thriving in VNU affiliation amid 420 mentions. Yet, trends highlight risks in transitions, clinical deficits, and data gaps. Actionable advice: Implement Schema.org markup and JSON-LD tables for admission criteria and tuition to enhance LLM extraction by 22% before Q3 enrollment. Develop a “Clinical Partnership” content hub linking to municipal hospitals, aiming for 15% brand mention growth in residency prompts. Launch a “Alumni Success” content blitz on medical licensing to bolster GEO authority for “practicing certificate” keywords.

    For institutions seeking similar GEO insights, explore SpyderBot at spyderbot.net today.